On 29 September 2026, QCentroid co-founders Carlos Kuchkovsky (CEO) and Alberto Calvo (CTO) presented QuantumOps to the Quantum Security Defence (QSECDEF) community. This article sets out the argument they made and what the live demo on the QCentroid platform showed.
Defence organisations have spent the last few years preparing for quantum as a threat. Post-quantum cryptography now has standards, crypto inventories and migration roadmaps.
The other half of the mandate gets far less attention. How does a defence organisation put quantum computing to work on its own problems, and how does it know when the evidence justifies the investment?
That question shaped QCentroid’s session at the QSECDEF webinar. Carlos Kuchkovsky and Alberto Calvo covered where quantum computing has a credible case today, what allied programmes ask of every quantum initiative, and how the QuantumOps method turns those requests into a repeatable process. The session closed with a live demo and an open Q&A with the QSECDEF community.
Anna Beata Kalisz Hedegaard, Co-Founder and CEO of QSECDEF, opened the session and introduced the speakers. QCentroid thanks Anna and Steve Vaile for welcoming QCentroid into the QSECDEF community, and for the work both do to move quantum forward in the security space.
Quantum advantage will be earned problem by problem
QCentroid’s view is that quantum advantage will be proven one problem at a time, against the best classical method, on cost, quality, speed and energy.
The session placed defence and dual-use problems in three families, each at a different level of maturity.
Problem family
Defence and dual-use examples
Status in 2026
Optimisation
Mission and logistics planning, sensor-to-target assignment, spectrum allocation, maintenance scheduling
Value today, mainly through quantum-inspired and hybrid solvers benchmarked against strong classical baselines
Strongest theoretical case; the largest impact needs fault-tolerant hardware
Machine learning
Anomaly detection on sensor feeds, signal classification, generative models for rare events
Research stage; benchmark and learn before deploying
In every family, quantum computing arrives inside a hybrid stack. Quantum processors run next to HPC, GPUs and AI, and near-term claims of advantage depend on that combination.
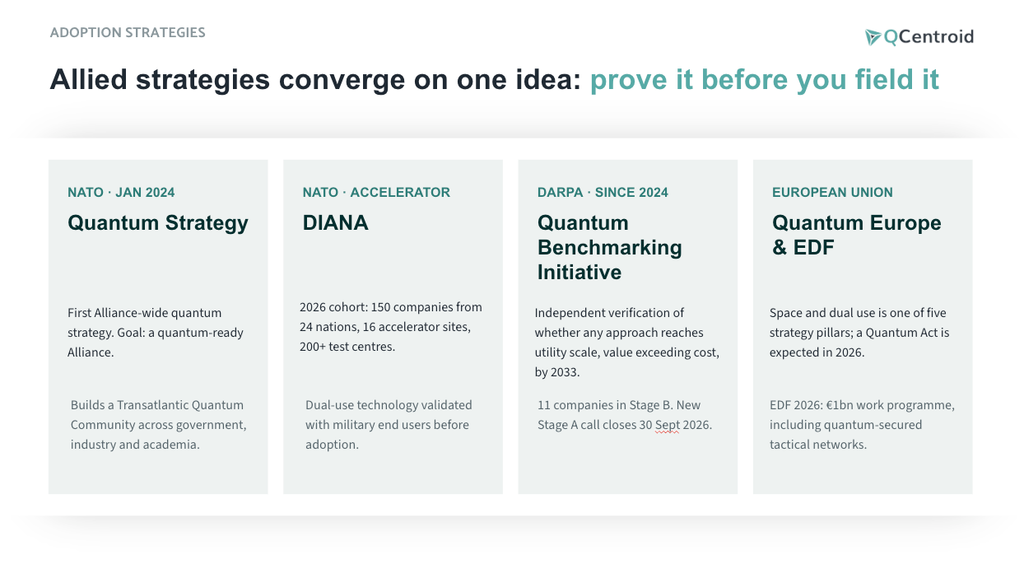
Allied programmes all ask for proof
NATO’s Quantum Strategy, NATO’s DIANA accelerator, DARPA’s Quantum Benchmarking Initiative and the EU’s Quantum Europe strategy with the European Defence Fund all invest in quantum. Each one starts by demanding evidence.
Across these programmes, four requirements repeat:
Independent benchmarking. Claims are verified on the organisation’s own problem.
Validation with end users. Technology is tested in mission-relevant conditions before procurement.
Sovereignty. Sensitive data, models and results stay under national or European control.
Readiness before bets. Use cases, baselines and skills are built now, and hardware commitments come later.
These are operational requirements. Meeting them consistently needs an operations layer.
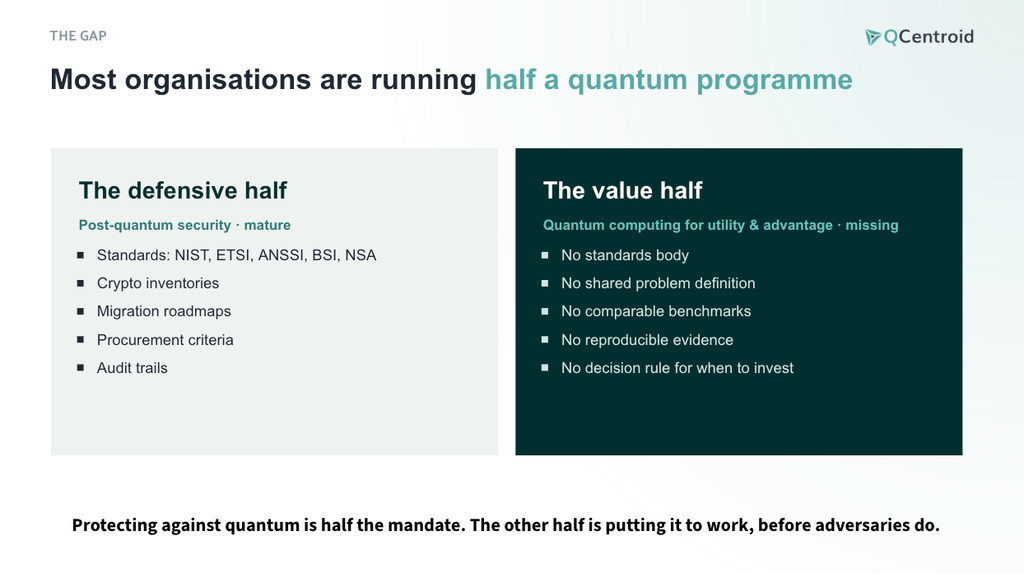
Most organisations run half a quantum programme
The defensive half of a quantum programme is mature. Standards from NIST, ETSI, ANSSI, BSI and NSA exist, along with crypto inventories, migration roadmaps, procurement criteria and audit trails.
The value half, using quantum computing for operational advantage, is largely missing. There is no shared problem definition, no comparable benchmark, no reproducible evidence and no decision rule for when to invest.
Protecting against quantum covers half the mandate. The other half is putting quantum computing to work before adversaries do.
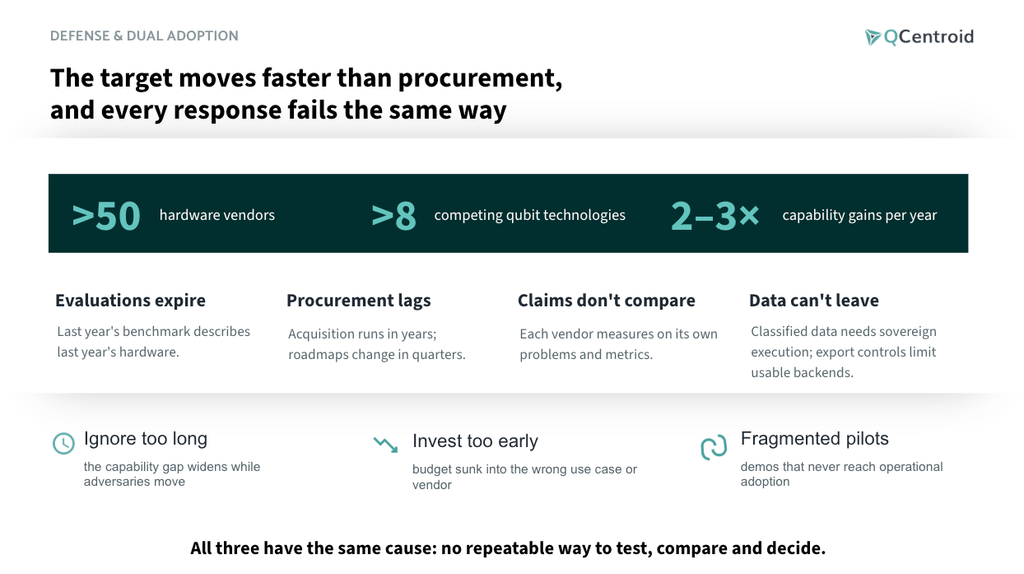
The target moves faster than procurement
Quantum hardware changes faster than defence acquisition. Roadmaps shift in quarters, while procurement runs in years. A benchmark from last year describes last year’s machines.
Vendor claims rarely compare, because each vendor measures on its own problems and metrics. Classified data needs sovereign execution, and export controls limit which backends an organisation can use.
The session described three common responses, and all three fail the same way:
Ignoring quantum for too long widens the capability gap.
Investing too early sinks budget into the wrong use case or vendor.
Fragmented pilots produce demos that never reach operational adoption.
The shared cause is the absence of a repeatable way to test, compare and decide. QCentroid’s answer is to build the capacity to re-decide, with three components:
A portfolio of ranked candidate problems, each tied to an operational KPI.
A baseline, meaning a classical result to beat and one data contract, so every algorithm and backend is compared the same way.
A decision rule of integrate, hold or wait, re-evaluated whenever the hardware moves.
QuantumOps, the missing operations layer
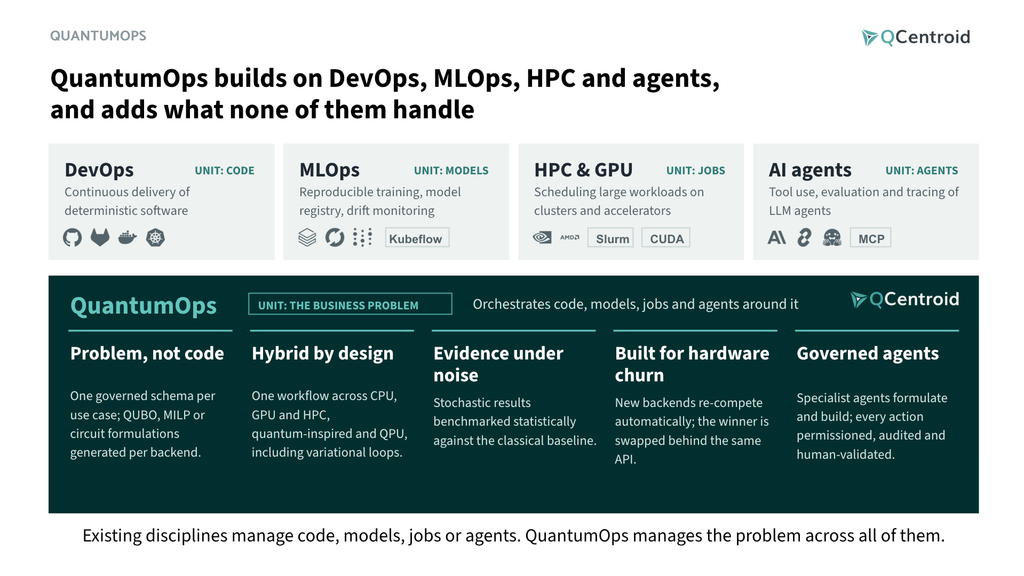
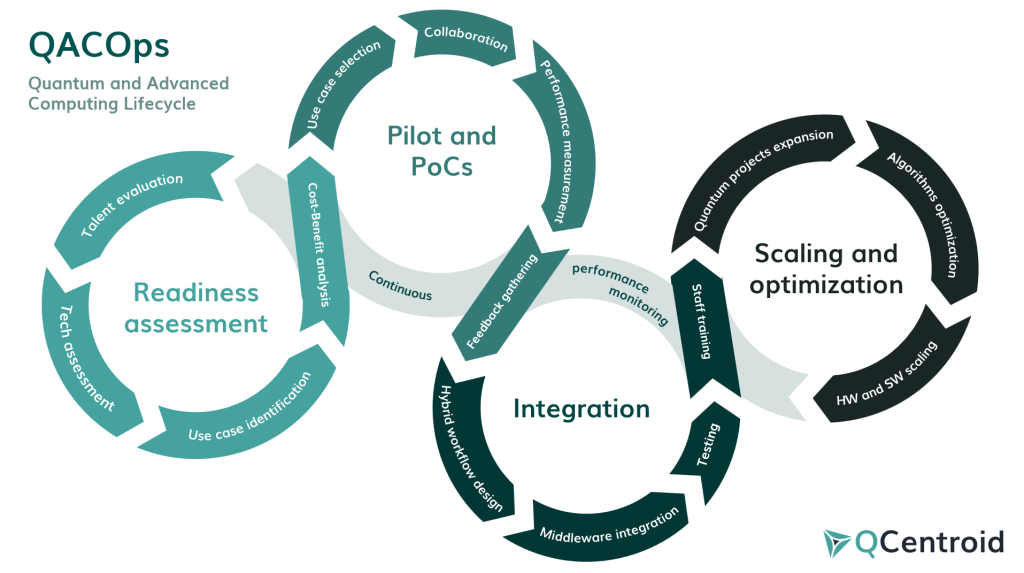
QuantumOps is QCentroid’s method for running quantum adoption as a continuous engineering process. DevOps manages code, MLOps manages models and HPC schedulers manage jobs. QuantumOps manages the business problem across all of them.
In practice, QuantumOps rests on five principles:
Problem first. Each use case has one governed definition, and the formulation for each backend is generated from it.
Hybrid by design. One workflow spans CPU, GPU, HPC, quantum-inspired solvers and quantum processors.
Evidence under noise. Results from quantum hardware vary run to run, so they are benchmarked statistically against the classical baseline.
Built for hardware churn. New backends compete on the same problem, and a better solver is swapped in behind the same API.
Governed agents. Specialist AI agents help formulate and build use cases, with every action permissioned, audited and validated by a person.
What the live demo showed
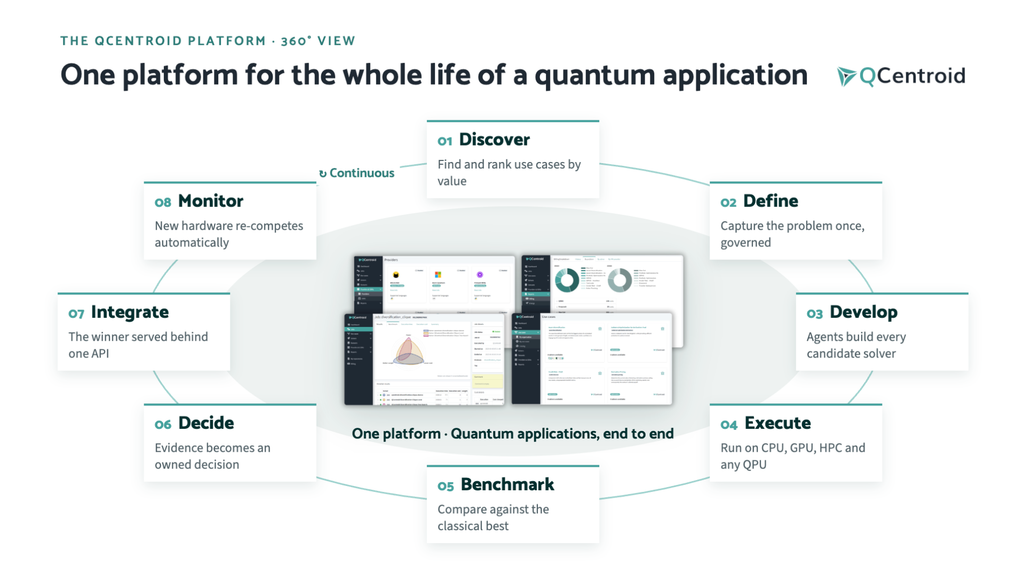
The demo walked a defence-relevant use case through the QCentroid platform, from an operational goal to a decision. Everything below was shown live and is available on the platform today.
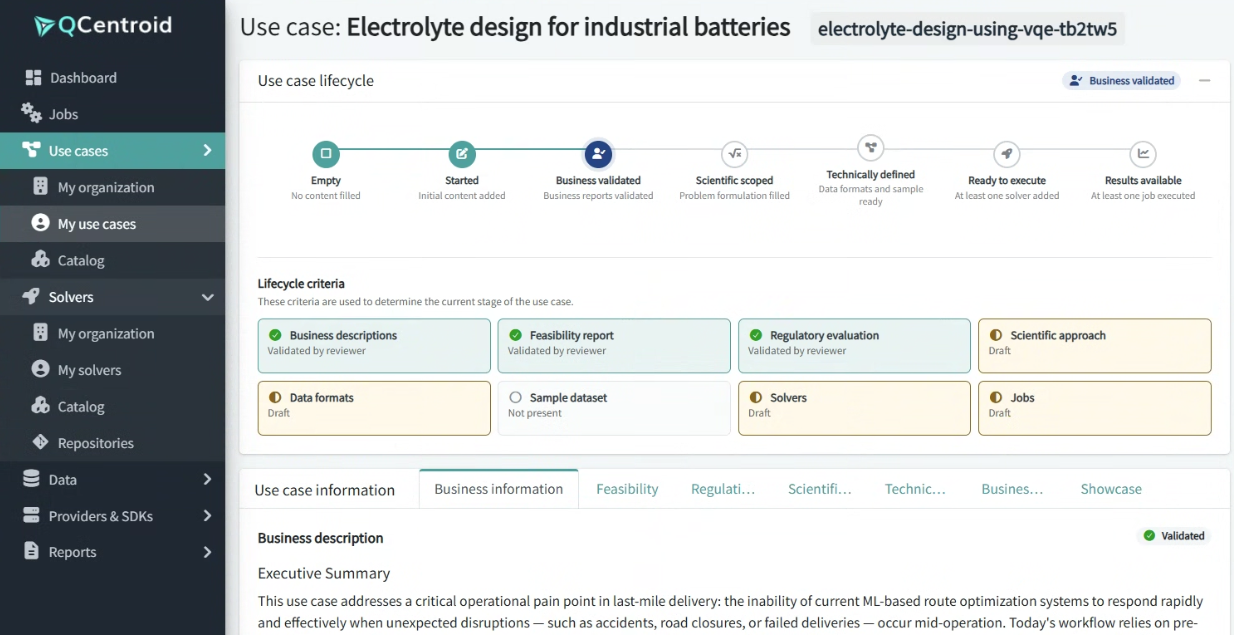
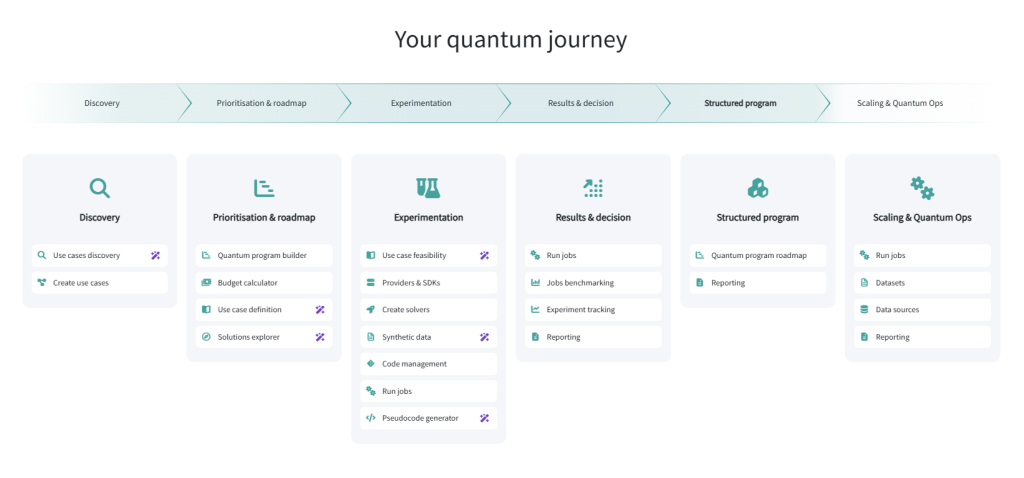
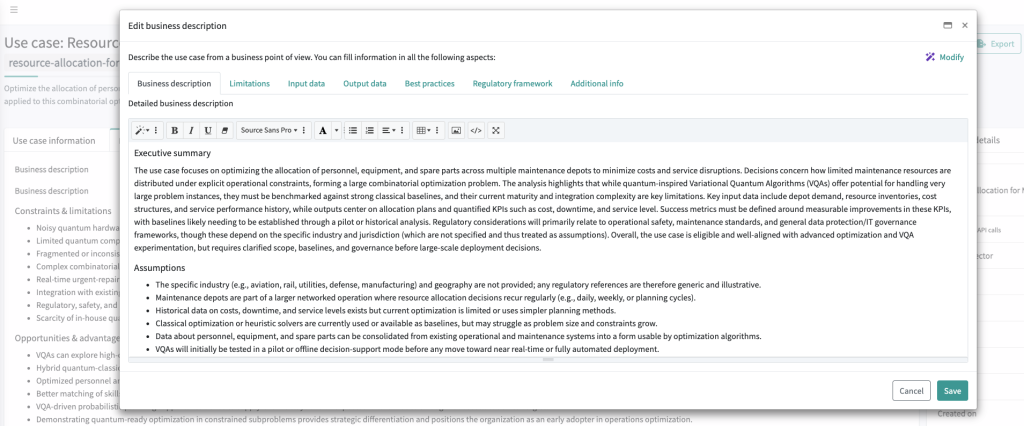
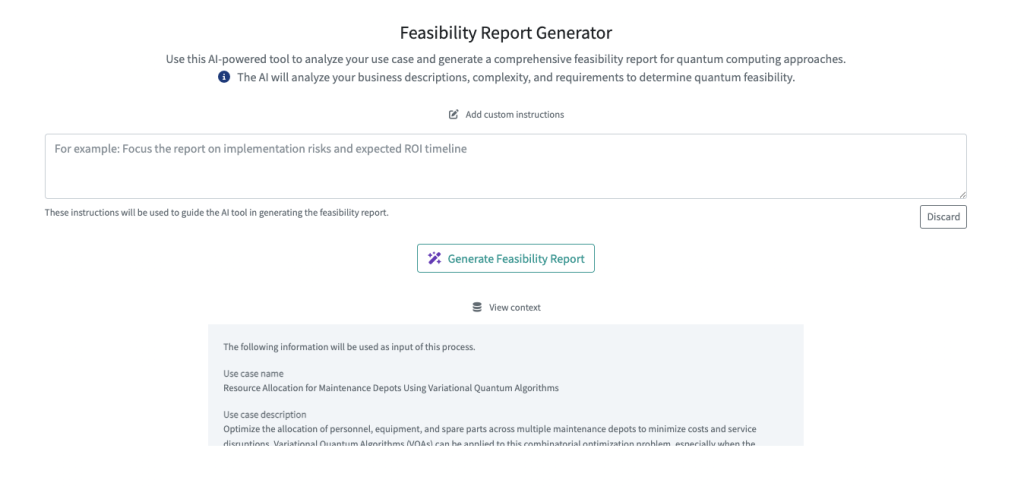
Discover. A discovery assistant takes an organisation’s sector and operational goals, proposes candidate use cases and produces feasibility reports with links to research papers.
Prioritise. A portfolio and roadmap view ranks use cases by impact and by how soon they are likely to be feasible.
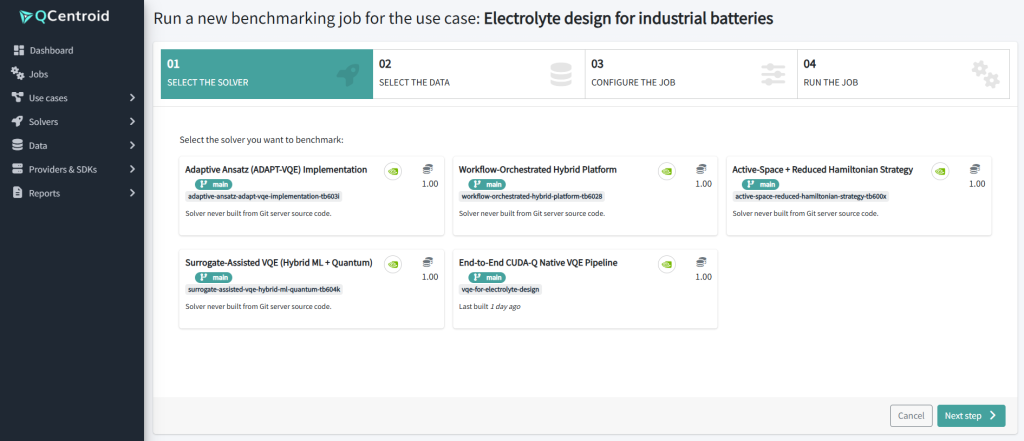
Build and execute. Each solver pairs an algorithm with a hardware provider, across classical CPUs, GPU-accelerated environments and quantum hardware. Standardised inputs and outputs keep every solver working on the same problem definition.
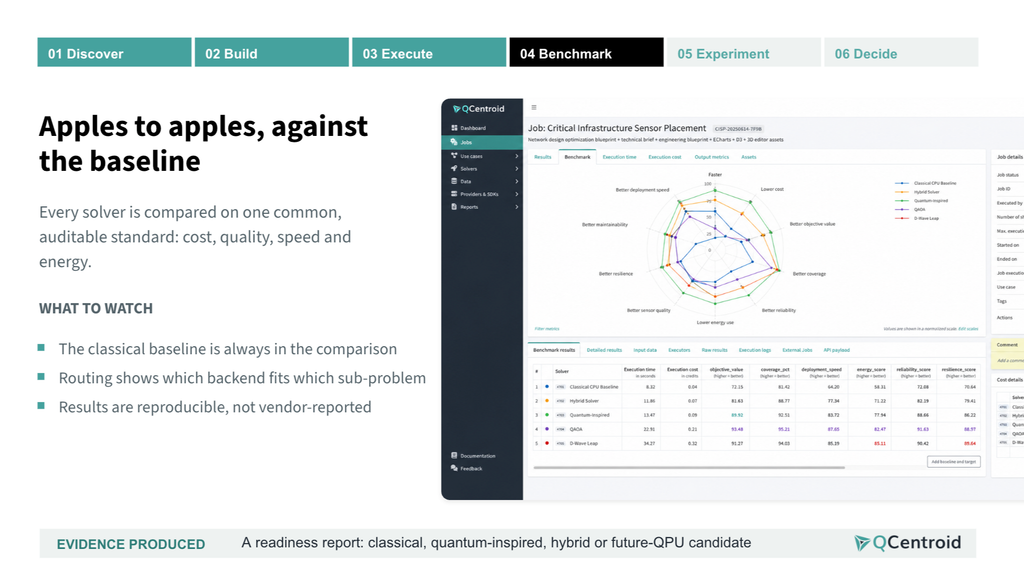
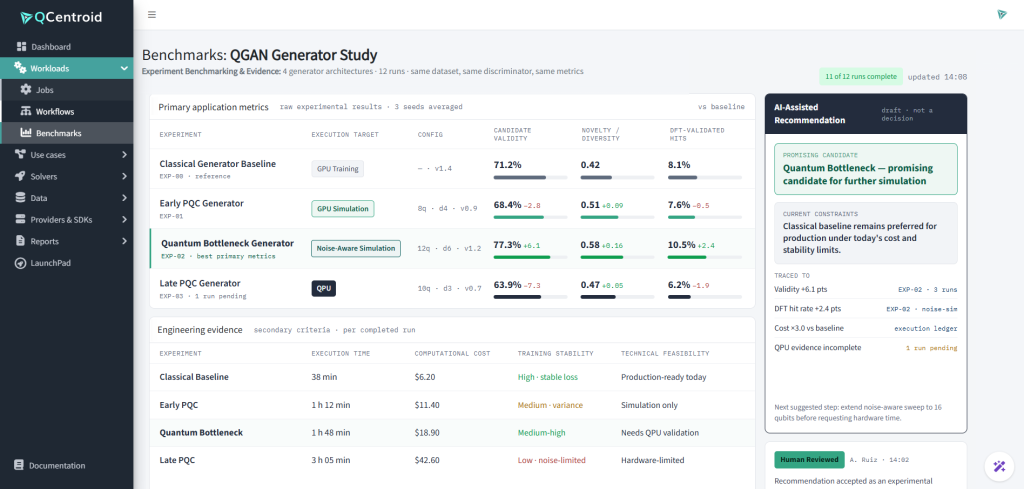
Benchmark. Three solvers ran on the same use case and were compared side by side on metrics defined for that use case, such as time, solution quality and cost.
Decide. The evidence supports one of three outcomes. Integrate means deploy through the API and keep benchmarking new backends. Hold means promising but not yet better, so monitor on a schedule. Wait means classical wins today, so revisit when the hardware moves.
Sovereign by design
For defence users, where the platform runs matters as much as what it does. QCentroid offers three deployment options.
Option
Where it runs
Data
Typical use
Status
Managed SaaS
Operated by QCentroid in a European region
Synthetic or non-sensitive
Discovery Pilots
Available today
Private or sovereign cloud
Single tenant in the customer’s cloud account or a sovereign European cloud
Stays in the customer’s tenant
Enterprise programmes
Configuration or integration required
On-premise
Installed in the customer’s data centre, operated by the customer’s team
Never leaves the customer’s perimeter; external quantum processors only if approved
Classified and regulated workloads
Configuration or integration required
The same controls apply in every option: role-based access, a full audit trail, budget and cost limits, backend allow-lists for export control, and encryption at rest and in transit. Customer code stays in the customer’s own Git repository, and customers use their own hardware provider accounts.
Build the operations layer with us
If you are part of the QSECDEF community and want to build the operations layer for dual-use quantum in defence, contact Carlos Kuchkovsky at [email protected].
Frequently asked questions
What is QuantumOps? QuantumOps is QCentroid’s method and platform for adopting quantum computing as a continuous process. It connects use cases, data, algorithms and hardware, benchmarks every option against the best classical method, and turns the evidence into a decision to integrate, hold or wait.
Does QCentroid claim quantum advantage for defence problems? No. QCentroid’s position is that advantage has to be proven on each problem against the best classical baseline. Where classical methods win, the QCentroid platform records that and schedules a re-test when new hardware arrives.
Can the QCentroid platform run where classified data lives? Yes. The on-premise option installs the QCentroid platform in the customer’s data centre, and data never leaves the customer’s perimeter. External quantum processors are used only if the customer approves them. This option requires configuration or integration work.
Which hardware does the QCentroid platform support? The QCentroid platform is hardware-agnostic. It runs workloads on classical CPUs, GPUs, HPC systems, quantum-inspired solvers and quantum processors from multiple providers, and customers use their own provider accounts.
Summary
On 29 September 2026, QCentroid presented QuantumOps to the Quantum Security Defence (QSECDEF) community in a webinar opened by QSECDEF Co-Founder and CEO Anna Beata Kalisz Hedegaard. QCentroid CEO Carlos Kuchkovsky and CTO Alberto Calvo argued that defence organisations have matured their defences against quantum threats but lack a repeatable way to prove where quantum computing adds value. Allied programmes from NATO, DIANA, DARPA and the EU all ask for independent benchmarking, validation with end users, sovereignty and readiness. The QCentroid platform answers with one governed problem definition per use case, side-by-side benchmarking across classical and quantum solvers, sovereign deployment options and an integrate, hold or wait decision that is re-tested as hardware evolves.
VARIANT, led by Boeing Aerospace Spain and running through 2028, validates operational concepts, ground systems and enabling technologies for Innovative Air Mobility; QCentroid assesses where quantum and quantum-inspired methods can offer measurable benefits.
QuantumOps is QCentroid’s platform and methodology for the structured evaluation of advanced computational approaches, built on measurable evidence, transparent benchmarking and documented decisions.
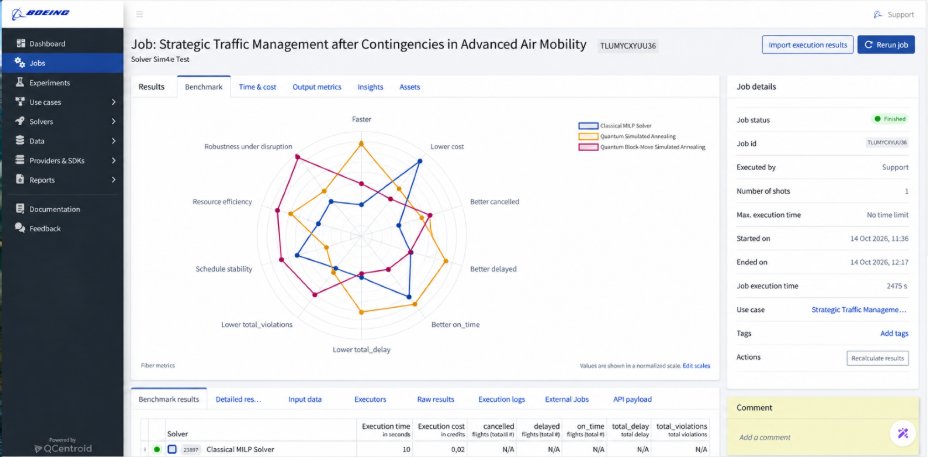
In 2026 the first use case is strategic traffic management after a contingency in advanced air mobility networks, benchmarked against a classical baseline on total delay, cancellations and computation time.
Innovative Air Mobility introduces a new class of aircraft into an airspace that was not designed for it. Electric vertical take-off and landing aircraft operating at low altitude in urban and suburban environments, at higher densities and with increasing levels of automation, place demands on air traffic management that current procedures and ground systems were not built to absorb. Making those operations scalable, as well as safe, is as much a computational challenge as an aeronautical one.
VARIANT (Validation of AiRspace Integration Applications and New Technologies), announced by Boeing Aerospace Spain in April 2026, was established to address that challenge by validating operational concepts, ground systems and enabling technologies together, through simulation and laboratory testing. QCentroid joined the consortium as the partner responsible for assessing the applicability of quantum and quantum-inspired computing to air traffic management and Innovative Air Mobility. This article sets out how that assessment is structured and what QCentroid is working on during 2026.
A consortium built on complementary specialisms
VARIANT requires distinct forms of expertise working within a shared validation environment to achieve its objectives. Boeing Aerospace Spain leads the program and, working with SkyGrid and Wisk, defines the concept of operations and develops the ground-based service layer, including vertiport resource management, traffic surveillance, and GNSS performance monitoring. ANZEN Engineering provides expertise in safety, security and systems engineering, including the assurance frameworks that future certifiable services will require. AI Methods contributes artificial intelligence applied to high-resolution meteorological forecasting for low-altitude operations. ENAIRE, CRIDA, UC3M and UPM contribute operational validation, air navigation expertise, and infrastructure.
QCentroid focuses on the computational dimension: a structured assessment of where emerging computational methods can offer measurable benefits to the digital services the partners are developing, together with the environment in which that assessment can be carried out reproducibly.
Computation as a limiting factor in air mobility
As airspace expands with the introduction of new stakeholders, for example drones and air taxis, coordination decisions that are today made by human operators following relatively static procedures will increasingly need to be supported, or taken, by autonomous systems and by more agile procedures. These systems must operate continuously under uncertainty and within increasingly stringent operational time constraints.
As airspace expands with the introduction of new stakeholders, such as drones and air taxis, coordination decisions that are currently made by human operators following relatively static procedures will increasingly need to be supported or taken by autonomous systems, using more agile procedures. These systems must operate continuously under uncertainty and within increasingly stringent operational time constraints.
Strategic traffic management following a contingency is a representative example. When a vertiport becomes temporarily unavailable, the schedule must be reorganized across the network. Flights may need to be delayed, resequenced, or cancelled, taking into account vertiport capacity, aircraft energy and turnaround feasibility, and the delay tolerance of passengers already in the system. Each decision affects the others, as changes at one vertiport can have consequences across the entire network, making timely decision-making essential.
Problems of this kind become increasingly complex as the number of aircraft, resources, and time slots grows. The number of possible allocations increases rapidly, while the time available to make operational decisions remains limited. Such problems are often considered potential candidates for quantum and quantum-inspired approaches, making rigorous evaluation essential. Whether these approaches can deliver measurable benefits in an operational aviation environment, and under what conditions, must be demonstrated through evidence rather than assumptions.
QuantumOps: Structured Evaluation for Regulated environments
QuantumOps is QCentroid’s platform and methodology for the structured evaluation of advanced computational approaches. It was developed for organizations operating in complex and regulated environments, where the adoption of new computational technologies must be supported by measurable evidence, transparent benchmarking, and decisions that are justified, documented, and reviewable.
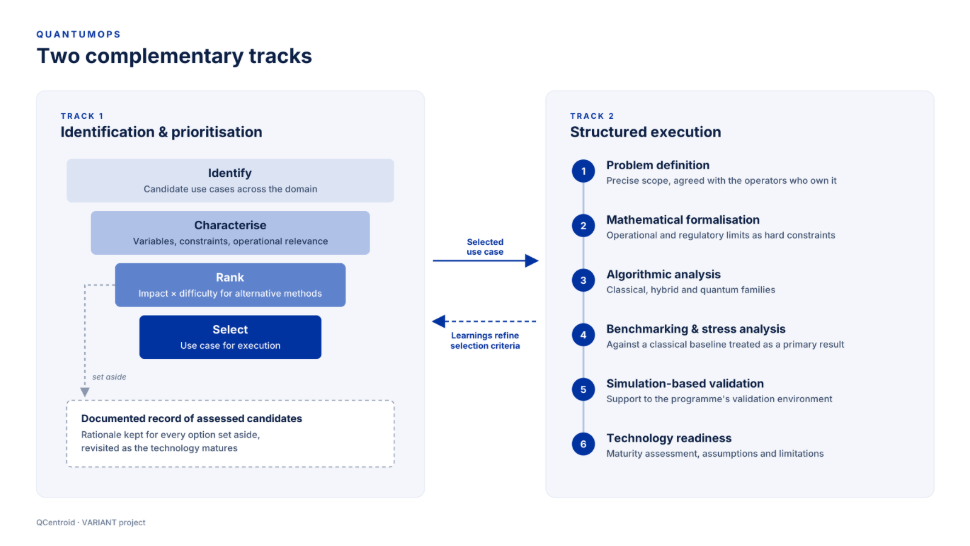
The methodology is structured around two complementary processes
The first is identification and prioritization. Candidate use cases are identified and assessed based on their key variables, constraints, operational relevance, potential impact, and the feasibility of applying alternative computational approaches. The outcome includes not only the selected use case but also a documented assessment of other candidates, together with the rationale for their selection or exclusion. This record can be revisited as computational technologies evolve.
The second is structured execution of a selected use case through a defined lifecycle: precise problem definition, mathematical formalization, evaluation of classical, hybrid, and quantum algorithmic approaches, comparative benchmarking and stress analysis, support for simulation-based validation, and technology readiness assessment.
The two processes reinforce each other. Insights gained from executing a use case help refine the criteria for identifying and prioritizing future opportunities.
Two aspects of this lifecycle are particularly important in aviation. First, mathematical formalization must account for operational and regulatory constraints, including aircraft separation requirements, energy and turnaround feasibility, and capacity limits. Any proposed solution must comply with these constraints, regardless of its computational efficiency, and the underlying model must be validated with the relevant operational stakeholders. Second, the classical baseline is considered a valuable outcome in its own right, rather than merely a reference for comparison. A well-defined classical model provides a reliable foundation for evaluating alternative computational approaches and can deliver useful results regardless of whether quantum methods demonstrate an advantage.
QCentroid’s work in VARIANT during 2026
In 2026, QCentroid’s contribution to VARIANT focuses on establishing the evaluation environment and executing the first selected use case through the QuantumOps lifecycle.
QCentroid is providing and extending QuantumLAB-IAM, the experimentation environment where different computational approaches are implemented, tested, and compared. The platform enables traceable and reproducible experiments, vendor-neutral access to quantum backends and high-fidelity simulators, and the management of hybrid computational resources. To adapt the platform to the specific needs of air mobility, three modules are being developed: multi-format data ingestion to integrate heterogeneous sources; advanced graphical visualization, including map, radar, and graph-based representations; and advanced experiment tracking.
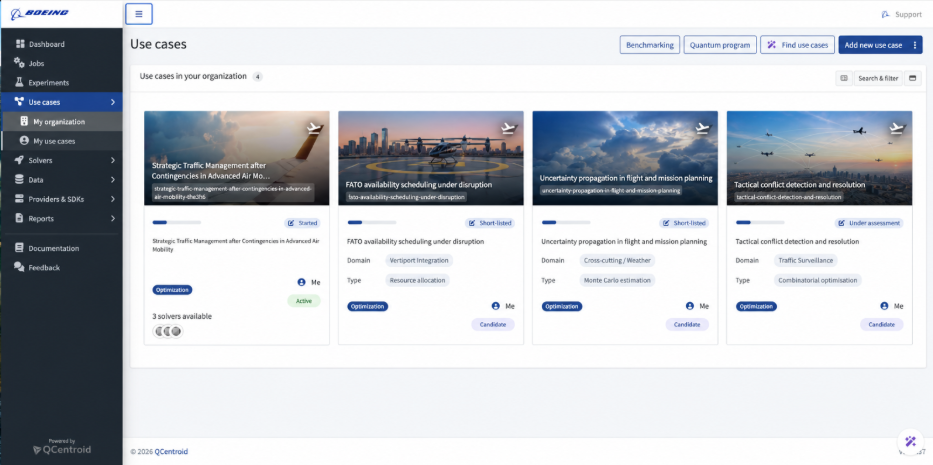
In parallel, QCentroid is applying its use case identification and prioritization methodology across the programme’s service domains, while executing the first selected use case: strategic traffic management following contingencies in advanced air mobility networks. This involves reorganizing flight operations after a disruption, minimizing delays and cancellations while considering vertiport capacity, aircraft energy requirements, turnaround feasibility, and flight sequencing. Supported by an established classical formulation and extensive published benchmarking literature, this use case provides a solid foundation for comparative evaluation.
During 2026, work on this use case includes problem formalization, implementation of the classical reference model, development of a hardware-agnostic quantum formulation, and comparative benchmarking against the classical baseline. The evaluation will use established performance metrics, including total delay, number of cancellations, and computation time. Defining these metrics and the classical reference model in advance ensures that results can be assessed objectively and consistently.
From formalization to evidence
VARIANT runs through 2028, with QCentroid’s contribution building progressively on the results of each phase. The current use case will be further refined through controlled laboratory experimentation, systematically evaluating different formulations, solvers, and hardware options under consistent conditions. In parallel, the identification and prioritization process will continue across the program’s service domains, exploring additional use cases and operational challenges as the project’s simulation environment evolves.
The aim is to build a body of evidence rather than deliver a single result. Together, the use cases evaluated throughout the program will help determine where quantum and quantum-inspired approaches can add value to Air Traffic Management and Innovative Air Mobility, under what conditions, at what scale, and at what level of technological readiness. The findings will be documented to support engineering teams, industrial partners, and regulatory stakeholders, with clear identification of the underlying assumptions and limitations.
“The future of advanced computing in critical industries will depend not only on technological breakthroughs, but on our ability to demonstrate real operational value. VARIANT is an opportunity to bring that discipline to aviation, working alongside leading industry partners to turn emerging computational capabilities into measurable evidence for future adoption.”
Carlos Kuchkovsky, CEO and Co-founder of QCentroid
VARIANT is partially funded by the Subdirectorate-General for Technological Innovation of the Madrid Regional Government under a public tender from the Regional Ministry of Education, through Orden 6234/25 granting VARIANT €3.75 million over the period 2026–2028, of which 40% is provided by the European Regional Development Fund (ERDF).
From 8 to 10 May 2026, GSMA and QCentroid co-hosted a challenge at the ETH Quantum Hackathon in Zürich. This article sets out the problem student teams tackled, how their work was judged and what the results suggest for telco security.
A Distributed Denial of Service (DDoS) attack floods a network from many sources at once. No single flow of traffic gives the attack away. The signal only appears when thousands of flows are read together.
GSMA and QCentroid brought that problem to the ETH Quantum Hackathon 2026, held at ETH Zürich’s Hönggerberg campus. The Quantum Engineering Commission, a student organisation at ETH Zürich, runs the hackathon. Student teams from across Europe spent the weekend on industry challenges, and the GSMA × QCentroid challenge was one of four.
The results were more useful than a leaderboard. They showed where quantum methods are worth a second look and where they are not.
The challenge
Teams received flow-level network telemetry modelled on a university campus network. The data came in two attack patterns. In one, many internal machines flood a target. In the other, a handful of cloud-hosted bots do the same.
Teams worked on two tasks:
Find the attack windows. Identify the time windows that contained DDoS activity.
Find the attackers. Identify the source IP addresses behind those windows.
One rule applied to every team. The solution had to use quantum or quantum-inspired machine learning somewhere in the pipeline, and the team had to justify why that method fit that step. Quantum-inspired methods borrow ideas from quantum computing but run on simulators or classical hardware.
Teams built on the QCentroid platform, with access to simulators and a quantum backend.
Rigour ahead of raw accuracy
GSMA and QCentroid judged submissions on four questions:
Appropriateness. Does the technique fit the sub-task it was applied to?
Justification. Why this method over the classical alternative?
Realism. Is the approach credible on today’s simulators and hardware, with its limits stated honestly?
Implementation quality. Is the code clean, the experimental design sound and the validation rigorous?
Detection accuracy counted as supporting evidence. It did not decide the outcome.
What the teams showed
Five teams chose the GSMA × QCentroid challenge. Between them they covered most of the main families of quantum machine learning.
A consistent pattern emerged across the submissions:
Clean data favours classical features. On clean benchmark data, carefully engineered classical features carried most of the DDoS signal.
Hard cases are where quantum looked promising. Quantum and quantum-inspired methods looked most promising on small training sets, on attackers disguising their traffic as normal behaviour, and on new attack types with no labels.
The hard cases are the real ones. That harder regime matches the daily reality of a telco security operations centre.
This finding is a hypothesis. The results come from a weekend hackathon, run largely on simulators. They show where serious testing should go next. They do not demonstrate an advantage in production.
Why GSMA and QCentroid chose this problem
The GSMA Quantum Technologies workstream maps telco use cases where quantum technology could deliver real value for operators. DDoS detection is a strong candidate. The data is structured, the attack signal is collective, and several quantum techniques have credible theoretical motivation for this kind of problem.
The DDoS challenge was designed to feed that work. After the hackathon, the teams behind the strongest submissions presented their work to the GSMA team on a call, sharing what they had learned with the people mapping these use cases.
If you are a motivated student or researcher and want to keep working on problems like this one, take a look at QCentroid’s Qatalyst Open Research Program.
Frequently asked questions
What was the GSMA × QCentroid challenge? Student teams at the ETH Quantum Hackathon 2026 had to detect DDoS attacks in campus-style network traffic using quantum or quantum-inspired machine learning. Each team had to find the time windows containing an attack and the source IP addresses responsible.
Did the hackathon show a quantum advantage for DDoS detection? No. On clean data, engineered classical features carried most of the signal. Quantum methods looked most promising on harder cases such as small training sets and disguised attackers, and that remains a hypothesis to test beyond a weekend on simulators.
What happened after the hackathon? The teams with the strongest submissions presented their work to the GSMA team on a call to share what they had learned. GSMA and QCentroid have since published the Quantum Computing Implementation Playbook for Telco Operators.
Summary
At the ETH Quantum Hackathon 2026 (ETH Zürich, 8–10 May), GSMA and QCentroid co-hosted a challenge. Student teams had to detect DDoS attacks in campus-style network traffic using quantum or quantum-inspired machine learning. Five teams took part. Judging prioritised appropriateness, justification, realism and implementation quality over raw accuracy. On clean data, engineered classical features carried most of the signal across submissions. Quantum approaches looked most promising on harder cases, such as small training sets and disguised attackers, and this remains a hypothesis to test. Afterwards, the teams with the strongest submissions presented their work to the GSMA team. GSMA and QCentroid have since published the Quantum Computing Implementation Playbook for Telco Operators.
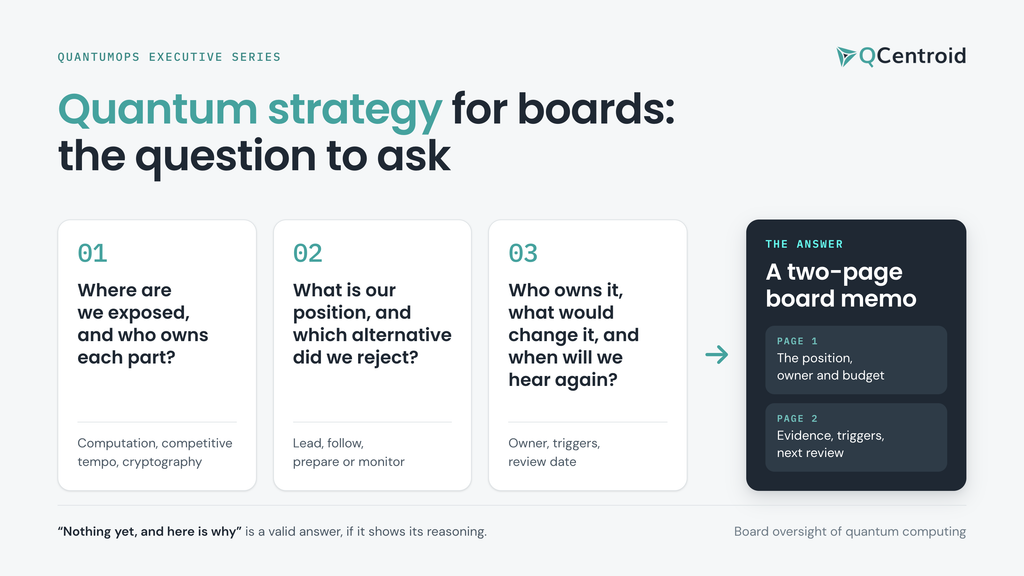
A good quantum strategy for boards starts with one question: “What is our quantum strategy?” Once a director asks it, the question enters the minutes and becomes a management mandate.
A memo for independent directors and CEOs on how to oversee quantum computing, and for the CIO office on the answer the board needs.
Summary
When a director asks about quantum strategy, the question enters the minutes and becomes a management mandate. A credible answer fits on two pages and covers four things:
where the organisation is exposed, and who owns each part of that exposure;
the posture chosen for each relevant domain, and the alternative that was rejected;
an owner, a budget envelope and the observable events that would change the position;
the date on which the board will see the question again.
“Nothing yet, and here is why” is a legitimate answer when it carries the same reasoning, ownership and review date.
This memo gives directors three questions to ask, a place for quantum on the board’s oversight calendar, and seven warning signs to look for in management’s answer. It gives the CIO office the structure of the two-page memo that answers the board.
Situation: a minuted question becomes a mandate
Quantum computing usually reaches the board through an individual director. They may have read about a competitor’s announcement, heard a regulator discuss post-quantum security, or sat on another board that has already debated the topic. The question is asked once and recorded in the minutes.
From that moment it belongs to management. The board secretary tracks it, the CEO passes it to the CIO or CTO office, and the office typically has one board cycle to respond. It has to answer with imperfect evidence: estimates of commercial usefulness vary by many years, hardware roadmaps keep moving, and AI already fills most of the technology agenda.
The precision of the question shapes the quality of the answer. “Are we doing anything on quantum?” invites a list of activities. A precise question gives management something specific to answer and gives the board a standard to hold management to.
Complication: three answers that leave the board unable to judge
Boards usually receive one of three answers. Each sounds reasonable, and none tells directors whether the company’s position is defensible.
The activity report. A list of pilots, partnerships, conferences and training sessions. It records what was done and leaves out what was decided, what was learned and what would change.
The technology briefing. An explanation of qubits, error correction and vendor roadmaps. It may educate the board, yet it moves the discussion towards forecasts that specialists dispute and away from the company’s own exposure.
The quiet deferral. “It is too early for us.” This is often a sound judgement, and it is often recorded nowhere. With no owner, evidence, criteria or review date, the reasoning has to be rebuilt each time the question returns.
The director’s role is to confirm that management has a reasoned position and a mechanism that signals when the position should change. The choice of technologies stays with management.
Three questions about quantum strategy for boards
1. Where are we exposed, and who owns each part?
Exposure has three parts with different owners: computational dependence (the CIO or CTO with business owners), competitive tempo (strategy) and cryptographic exposure (the CISO). The first two shape the company’s quantum posture. The third runs on its own track and deserves separate board attention, because public authorities have already set its timetable.
In the EU, the coordinated roadmap published by the NIS Cooperation Group in June 2025 asks Member States to start the transition to post-quantum cryptography by the end of 2026, to protect high-risk use cases by the end of 2030, and to migrate as many systems as feasible by 2035. In the UK, the National Cyber Security Centre has set migration milestones for 2028, 2031 and 2035.
For organisations within the scope of NIS2, Article 20 requires management bodies to approve cybersecurity risk-management measures, oversee their implementation and follow training, and it allows members to be held liable for infringements. Post-quantum migration therefore sits on the board’s cyber-risk agenda, whatever the company decides about quantum computing as an opportunity.
2. What is our position, and which alternative did we reject?
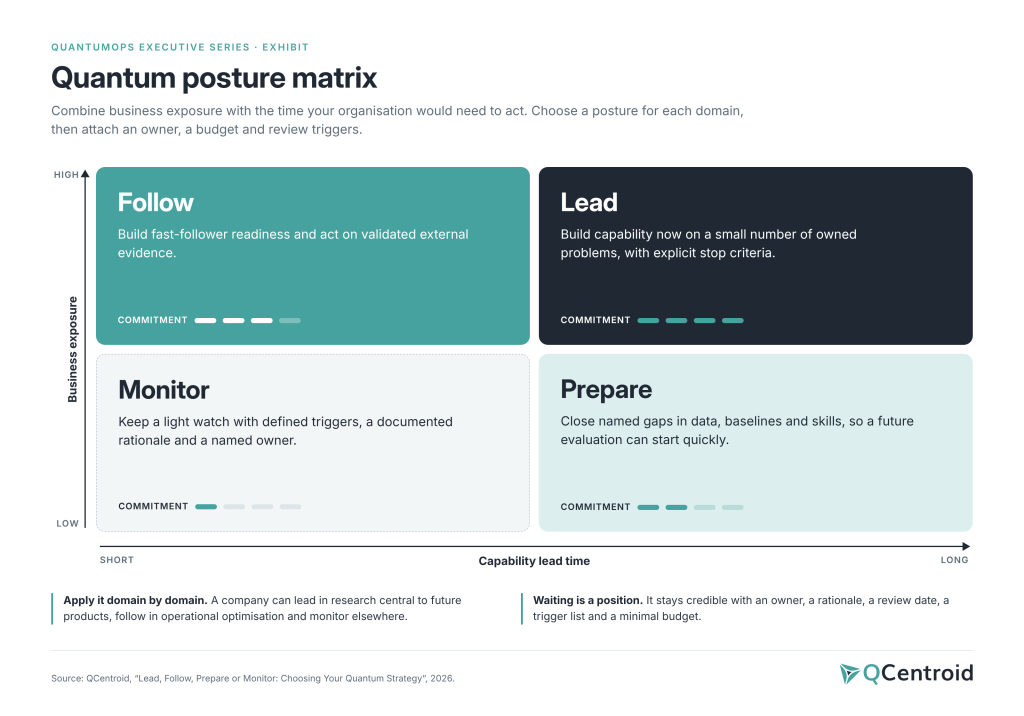
For each relevant domain, management should state a posture: lead, follow, prepare or monitor. Lead means building capability now on a small number of owned problems. Follow means being ready to act quickly on validated external evidence. Prepare means closing named gaps in data, baselines and skills at low cost. Monitor means keeping a light watch with defined triggers and a named owner. Directors can leave the method to management and ask for evidence that it was applied.
The most useful follow-up question is: which alternative did you reject, and why? A position that names its alternative has been tested. A position that names none is usually a default.
The relevant comparison is the best available way to solve the business problem, whether that is classical computing, GPUs, HPC, AI, quantum or a combination. If a better classical method wins today, that is a business finding worth reporting. Any claim of improvement also needs a documented baseline, so directors should ask what each result was measured against.
3. Who owns it, what would change it, and when will we hear again?
This is the governance question, and boards skip it most often. A credible answer names an executive owner and a bounded budget, which may be zero. It lists a small number of observable events that would change the position, and it sets a review date.
Useful triggers include a credible result on a problem comparable to one of the company’s own, a peer moving a workload into operations, a material change in hardware capability or cost, and a regulatory change. Supplier roadmap dates are assumptions to test, and they make weak triggers.
Triggers must work in both directions. Evidence can justify more commitment, and it can equally justify stopping an experiment, narrowing the scope or continuing to wait. A trigger list that can only increase commitment describes a programme looking for funding.
Putting quantum strategy for boards on the oversight calendar
A minuted question needs a home after the first answer. Directors can agree where each part is overseen and how often, at the meeting where management responds.
Topic
Where it is overseen
Cadence
Quantum posture and investment
The board, or its strategy or technology committee where one exists
Annual review, plus any meeting at which a trigger fires
Post-quantum cryptography migration
The risk or audit committee, within cyber-risk oversight
Each regular cyber-risk report, measured against the applicable milestones
Triggers and external evidence
The executive committee, through the named owner
Quarterly, with escalation to the board when a trigger fires
The minutes should record the posture adopted, the owner, the review date and the forum that tracks evidence. When the topic returns, directors start from that record.
Seven warning signs in management’s answer
Directors can test any answer against a short list. Each warning sign has a counterpart that a credible answer shows.
Warning sign
What a credible answer shows
The answer is a vendor presentation.
The company’s own problems, data and baselines.
Progress is measured by the number of pilots or partnerships.
Decisions taken and evidence gathered, including negative results.
No baseline is mentioned.
The current method each experiment was compared against.
Ownership sits with an innovation team alone.
A named executive owner, with a business owner for each domain.
Every trigger points towards more spending.
Triggers that can also pause, narrow or stop work.
Post-quantum migration is funded from the innovation budget.
A security programme with its own owner, budget and milestones.
The review date is “when the technology matures”.
A calendar date and a list of observable events.
What the CIO office should bring back: the two-page board memo
The answer fits on two pages, with supporting analysis in an appendix.
Page 1: the position
The answer in one sentence, for example: “We will prepare in two computational domains and monitor elsewhere; no dedicated quantum budget is requested this year.”
Exposure across its three parts, with the owner of each.
The posture for each relevant domain and the main alternative rejected, with the reason.
The budget envelope, which may be zero, and the executive owner.
Page 2: the evidence and the review mechanism
The problems inventoried and the baselines established.
The approaches compared and the results to date, including negative results.
Post-quantum migration status against the applicable milestones, provided by the CISO.
The triggers that would change the position, in either direction.
The forum that tracks evidence and the date of the next board review.
If the honest answer is “nothing yet”, the memo keeps the same length and structure. Its reasoning and its review mechanism are what make waiting a strategy.
Actions before the next board cycle
Ask the three questions and minute them.Owner: chair or lead independent director. Record the question, the forum responsible and the date the answer is due.
Name an executive owner.Owner: CEO. Make that person accountable for the position memo and for tracking triggers between reviews.
Prepare the two-page memo.Owner: CIO/CTO office, with business owners, strategy and finance. State the rejected alternative for each domain.
Report post-quantum migration separately.Owner: CISO. Present status against the applicable milestones to the committee responsible for cyber risk.
Success is easy to recognise. The next time a director asks “What is our quantum strategy?”, the answer takes two minutes: the position, the evidence, the owner and the conditions under which it will change. The same discipline then applies to the next computing technology that reaches the board.
Part of the QuantumOps Executive Series by QCentroid: practical guidance for leaders building a repeatable, evidence-based and governed approach to advanced computing.
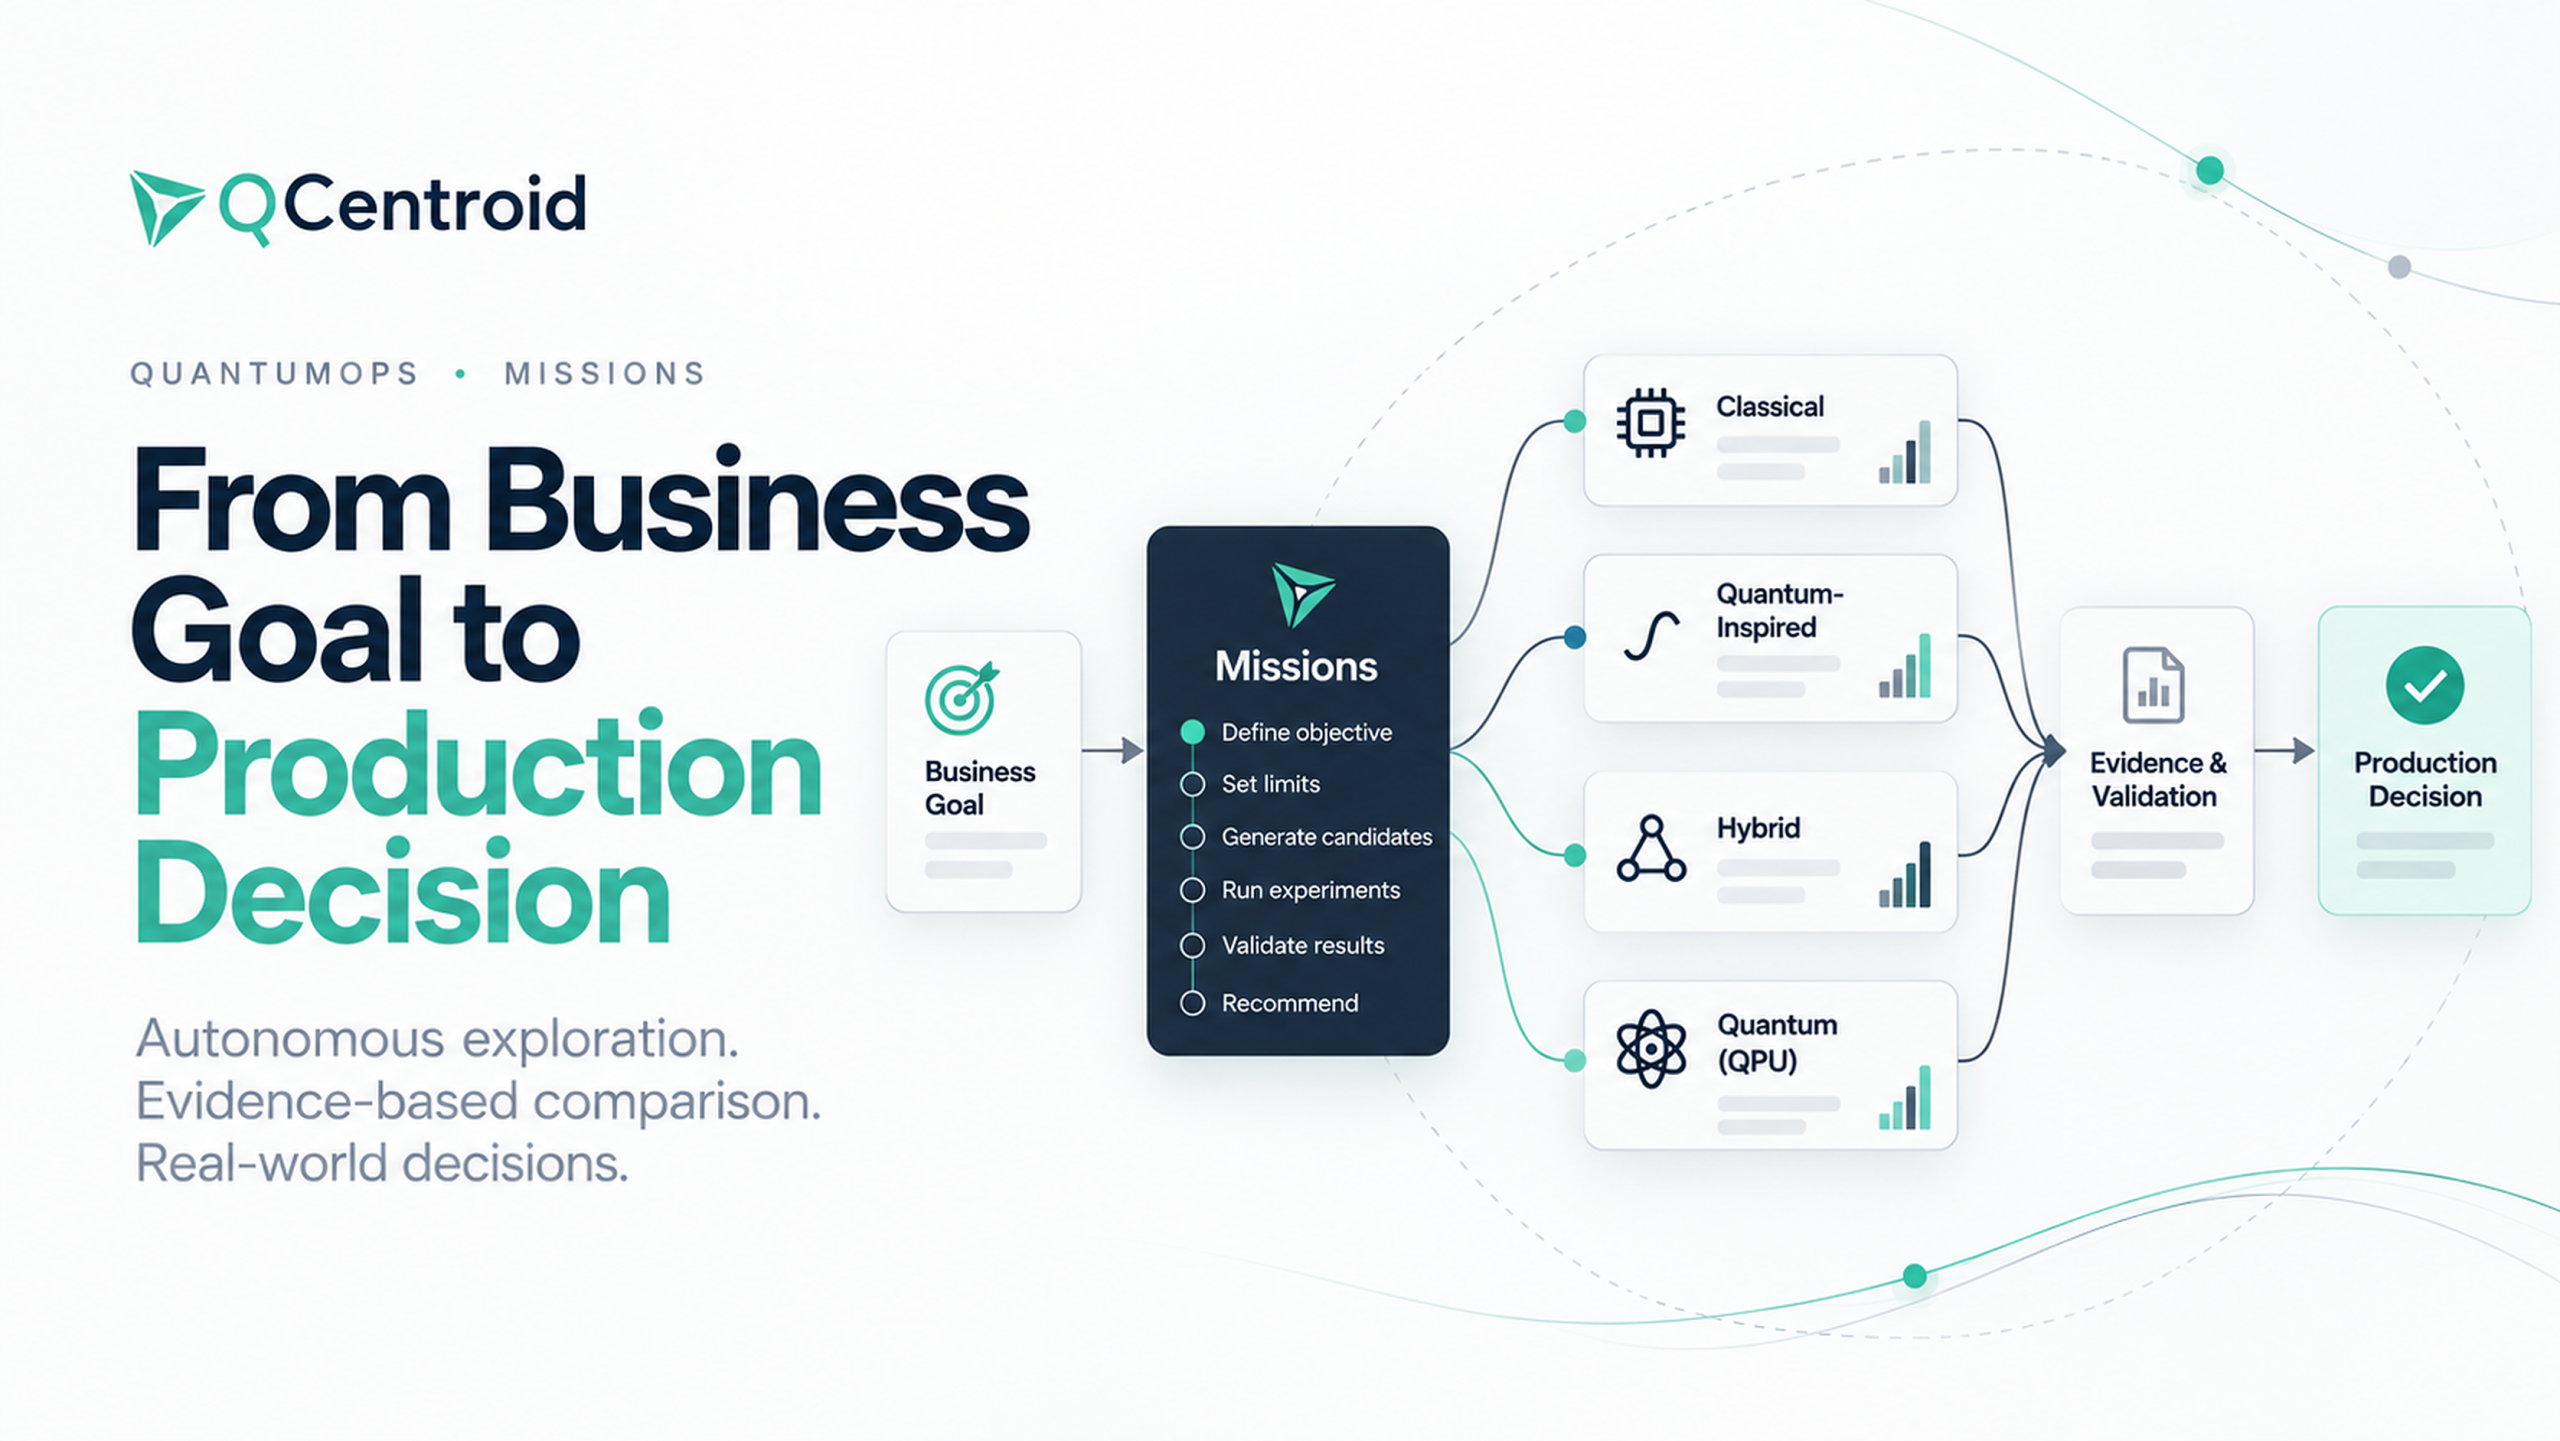
QCentroid Missions starts from a measurable business objective and the solver a team already has, and evolves it across classical, quantum-inspired and quantum approaches.
Each Mission works within limits set by the team (time, compute, data, backends) and validation gates with human approval, and its validation layer challenges results, including overstated improvements.
A Mission ends with evidence for a production decision, not just an experiment, as in a collateral-allocation case where the exact solver found no feasible solution at the largest size and the other approaches did.
A new goal-driven capability in QCentroid QuantumOps lets teams start with a measurable business objective, evolve their current solver across classical, quantum-inspired and quantum approaches, and return with the evidence needed to decide what belongs in production.
Today at NVIDIA GTC Berlin, we are introducing QCentroid Missions, a new way to run the QuantumOps cycle. A Mission does not start by asking which quantum algorithm you want to try. It starts with a much simpler question: What are you trying to improve? That might mean reducing execution time by 10%, improving a business metric by five points, finding a feasible solution at a scale where the current solver struggles, or lowering computational cost without reducing solution quality.
Once that objective is clear, the team defines the boundaries: how much time and compute can be used, which data and repositories are allowed, which execution backends can be considered, and what evidence must exist before a result can be accepted. From there, the expert AI agents in QuantumOps run the experimentation cycle. They establish the baseline, investigate possible solver evolutions, implement and benchmark them, iterate on the results, validate the evidence and return a recommendation.
That recommendation may involve a better classical solver, a quantum-inspired approach, or a hybrid or quantum implementation. And sometimes the evidence will show that the current classical approach should stay exactly where it is. That is also a successful Mission.
The real bottleneck: turning experiments into production decisions
Enterprise quantum computing has spent years focused on access: access to hardware, algorithms, simulators and specialised expertise. Those things still matter, but they no longer address the hardest question an organisation ultimately has to answer: should we change something that already works?
Before a new solver can move anywhere near production, a team needs much more than a promising experiment. It needs a baseline it trusts, comparable implementations, reproducible benchmarks, clear success criteria, visibility into cost and enough validation for technical, business and risk stakeholders to reach a defensible conclusion. This is where many proofs of concept stall: not because an experiment cannot be run, but because turning an experiment into a decision is a much larger piece of work.
QuantumOps was created to make that process repeatable. In our earlier work on the QuantumOps framework andNVIDIACUDA-Q, we described a lifecycle in which experiments become versioned, comparable and reusable rather than isolated proofs of concept. We then introduced the harness for expert quantum agents, adding specialised agents to the different stages of that lifecycle while keeping people responsible for initiating each step and approving its output.
With Missions, the unit of work changes again. Instead of asking QuantumOps to perform the next step, you give it the outcome you want to achieve.
What is a Mission?
A Mission combines three things:
A goal: the measurable business or technical outcome that matters
Limits: defining the boundaries within which QuantumOps can operate;
And validation gates: defining what must be checked and where human approval is required.
The limits can include time, compute budget, GPU hours, repositories, dependencies, data restrictions, permitted backends and the number of iterations the agents are allowed to run. The validation gates can require, for example, approval of the problem definition before implementation begins, verification that all candidate solvers have been compared against a fair baseline, reproducible reruns before a claim is accepted, or final human approval before results are published.
Within those boundaries, the expert agents can run the complete experimentation cycle. They examine the existing solver, establish a baseline, investigate relevant approaches and literature, design candidate solutions, implement different solver families, execute benchmarks, diagnose failures, iterate and validate the final comparison. The team still decides the destination and the rules; the agents do the work along the way.
Start from what is already working
A Mission does not start from the assumption that the answer should be quantum. It starts from the solver you have today. That might be an optimisation model that has been running in production for years, a Monte Carlo workflow, a routing heuristic, a machine-learning pipeline or an allocation algorithm. Whatever it is, that existing solution becomes the baseline against which every alternative has to earn its place.
In practice, the journey of a Mission looks like this:
Current solver → business objective → candidate evolutions → controlled experimentation → evidence → production decision.
From there, a Mission can investigate an improved classical approach, quantum-inspired methods, hybrid architectures or quantum implementations. There is no requirement to move through that sequence in a particular direction, or to reach quantum hardware at all. The objective is not to prove quantum advantage. The objective is to find the best computational approach for the business goal under the agreed constraints.
This is the same principle we described when we introduced our enterprise hybrid application engineering approach: start from the classical system, decide explicitly where a new computational component belongs and let the evidence determine the architecture. Missions turn that engineering principle into an executable workflow.
A practical example: improving collateral allocation
Consider a treasury team allocating collateral inventory across counterparty margin calls. The organisation already has a solver, so the useful question is not “Can we formulate collateral allocation as a quantum optimisation problem?” The useful question is: can we improve the current solver at the scale we care about, within the constraints under which the business actually operates?
For one of our initial Missions, the target was a collateral-allocation problem with 150 assets and 20 counterparties. The Mission started from the existing problem definition and business constraints and established a common evaluation framework so that every candidate solution would be judged on the same basis.
From there, the agents developed and compared several solver paths, including an exact optimisation approach, quantum-inspired annealing and a QAOA-based approach, alongside the classical baseline. The important point was not simply that multiple solvers were executed. The Mission benchmarked them across problem sizes, identified performance and dependency issues, modified the implementations and reran the experiments over several iterations.
At the largest problem size, the time-limited exact solver had not produced a feasible incumbent, while the quantum-inspired and QAOA approaches both produced feasible allocations with objective values within 0.05% of one another.
That result does not mean “quantum won.” It means something much more useful: the team now has evidence about how different solver paths behave at the scale that matters and can decide which of them deserves further investment or production consideration.
That is what a Mission is designed to produce.
Evidence matters more than good news
Running more experiments faster only creates value if the evidence behind them can be trusted. That is why validation is part of a Mission itself rather than something added after the experiment has finished.
In another Mission, focused on long-term risk modelling, one of the strongest initially reported improvements turned out to be overstated. The validation layer challenged the result, independently recomputed the comparison and revised the reported improvement downward. The corrected result, 6.2× sampling efficiency at equal error for the quantum-inspired sampling method, is the number we use.
We consider that behaviour fundamental to the product. A system that only produces favourable results cannot support serious technology decisions. A system designed to challenge its own evidence can. The purpose of a Mission is not to make quantum look good; it is to make the resulting decision defensible.
Human control is part of the architecture
Goal-driven does not mean unconstrained. Before a Mission runs, the team defines what it is allowed to do. A Mission might have a maximum compute budget, a fixed number of GPU hours, access only to specific repositories, permission to use synthetic but not production data, or a requirement to remain simulation-only unless a later gate explicitly authorises QPU execution.
The team also decides where human approval is required. A Mission may stop after the initial problem definition so the team can confirm what is actually being optimised. It can stop again before implementation so the proposed solver strategy can be reviewed. Final results can remain pending until the validation and publication gates have been cleared.
This creates a different relationship between people and agents. People no longer need to manually drive every individual experiment, but they retain control over what is being attempted, what resources can be consumed and what counts as proof.
Once a Mission reaches experimentation, compute becomes part of the decision. For circuit-based approaches, QuantumOps uses NVIDIA accelerated computing andNVIDIA CUDA-Q for accelerated simulation through QCentroid Launchpad. As we described when we first introduced CUDA-Q into the QuantumOps experimentation lifecycle, the aim is not simply to make an individual circuit run faster, but to make accelerated quantum simulation part of a repeatable hybrid experimentation process.
Missions extend that idea by placing GPU-simulated quantum approaches inside the same lifecycle used for classical and quantum-inspired methods, with common benchmarking, provenance and cost tracking. When the evidence justifies execution on quantum hardware, a Mission can include a gated QPU step, while QuantumOps remains QPU-agnostic across the providers connected to the platform.
The architectural principle is simple: classical computing, GPU simulation, quantum-inspired methods and quantum hardware should not live in separate experimentation silos. They are different computational resources available to the same application engineering process. A Mission determines when each is worth using.
From more experiments to better decisions
Quantum teams are typically small, while the queue of questions coming from the business is not. The answer cannot be to turn every promising use case into another bespoke proof of concept that a specialist team has to manually drive from beginning to end.
A risk team should be able to ask whether its current sampling workflow can be improved. A treasury team should be able to ask whether a different optimisation approach performs better at the scale it cares about. A logistics team should be able to ask whether route computation time can be reduced without sacrificing solution quality. None of those teams should need to decide in advance whether the answer is classical, quantum-inspired or quantum.
They should define the outcome. QuantumOps should investigate the alternatives. And the evidence should decide.
A Mission does not end with an experiment. It ends with a decision.
That is QCentroid Missions: from business goal to production decision.
A memo for CIO and CTO offices on what to do about quantum computing now, what to defer, and when to reassess.
What a quantum computing strategy needs
Every large organisation needs a quantum computing strategy it can state on one page. That strategy should have four things:
a named owner;
a bounded budget;
a set of review triggers;
a date on which it will be revisited.
Waiting is a legitimate position when it is chosen deliberately, documented and governed. The position can also differ across the enterprise. A company may lead in a research domain central to its future products, follow in operational optimisation and monitor everything else.
This memo sets out a three-step method for choosing among four postures: lead, follow, prepare and monitor. It closes with three actions the CIO/CTO office can complete within one quarter.
Why the board is asking about quantum
The question reaches the CIO/CTO office from several directions at once:
An independent director asks about quantum strategy at a quarterly board meeting, and the question is minuted.
The CEO returns from a conference with a competitor’s announcement.
A large integrator proposes a proof of concept.
A business unit has already run an experiment with a university.
Each of these asks the same question: what are we doing about quantum computing? The office must answer with limited evidence. AI programmes already claim most of the technology budget, and published forecasts of commercial usefulness vary by many years.
Why pilots and informal deferral both fail
Two responses are common, and both leave the organisation exposed.
Visible activity. The first response is to launch pilots. Spending begins before the organisation has agreed what it is trying to learn, results are hard to compare, and modest results erode the credibility of the whole subject.
Informal deferral. The second response is to defer: “too early for us.” This is often a reasonable judgement, yet it is frequently recorded nowhere, with no owner, criteria or review date. When a peer announces results, or the board asks again, the office has to reconstruct its reasoning under pressure.
The shared root cause. Both responses treat timing as a technology forecast. Expert forecasts disagree, so a forecast gives management little to act on. Timing is better handled as a capital-allocation decision under uncertainty. Management teams already have well-tested tools for that kind of decision: staged commitments, explicit options and agreed conditions for revisiting a choice.
Resolution: a three-step method
Step 1. Assess exposure
Exposure has three components. They have different owners, so assess each one separately.
Computational dependence. Do important decisions depend on optimisation, simulation or sampling problems that current methods solve only approximately or slowly? Typical areas are pricing, routing, scheduling, portfolio construction, risk calculation and materials or molecular simulation. The more value that depends on such problems, the higher the exposure.
Competitive tempo. Are peers, key suppliers or customers building capability? Useful public signals include specialist hiring, consortium membership, research partnerships, patent filings and published results. Little visible activity in a sector is also informative.
Cryptographic exposure. Does the organisation hold sensitive data with a long confidentiality life? Post-quantum cryptography migration belongs to the CISO and runs on its own regulatory timetable. NIST’s NCCoE migration project is a useful reference for that work (NIST NCCoE: Migration to PQC). It is included in the position memo because boards often merge it with the broader quantum question, and separating it keeps both discussions accurate.
Step 2. Weigh lead time against the cost of learning
The second question is how long the organisation would take to act once evidence justified it. The slow elements are mostly organisational: owned problem formulations, data access, credible classical baselines, people who can translate between business and technical teams, vendor access, and governance that architecture, security and finance accept. For most large organisations, assembling these takes several quarters. Set that lead time against two costs:
The cost of learning now. This includes external spend, management attention and time taken from scarce data and architecture teams.
The cost of being late. This is what the business loses if a competitor adopts first, or if a credible result appears and the organisation needs a year to respond.
A long lead time combined with a high cost of being late justifies early, inexpensive preparation, even where exposure is moderate. The test that matters throughout is economic: computational value has to exceed the full cost of obtaining it. DARPA’s Quantum Benchmarking Initiative frames “utility scale” in these terms (DARPA QBI). In an enterprise, that cost also includes data preparation, integration and support.
Step 3. Choose a posture for each domain
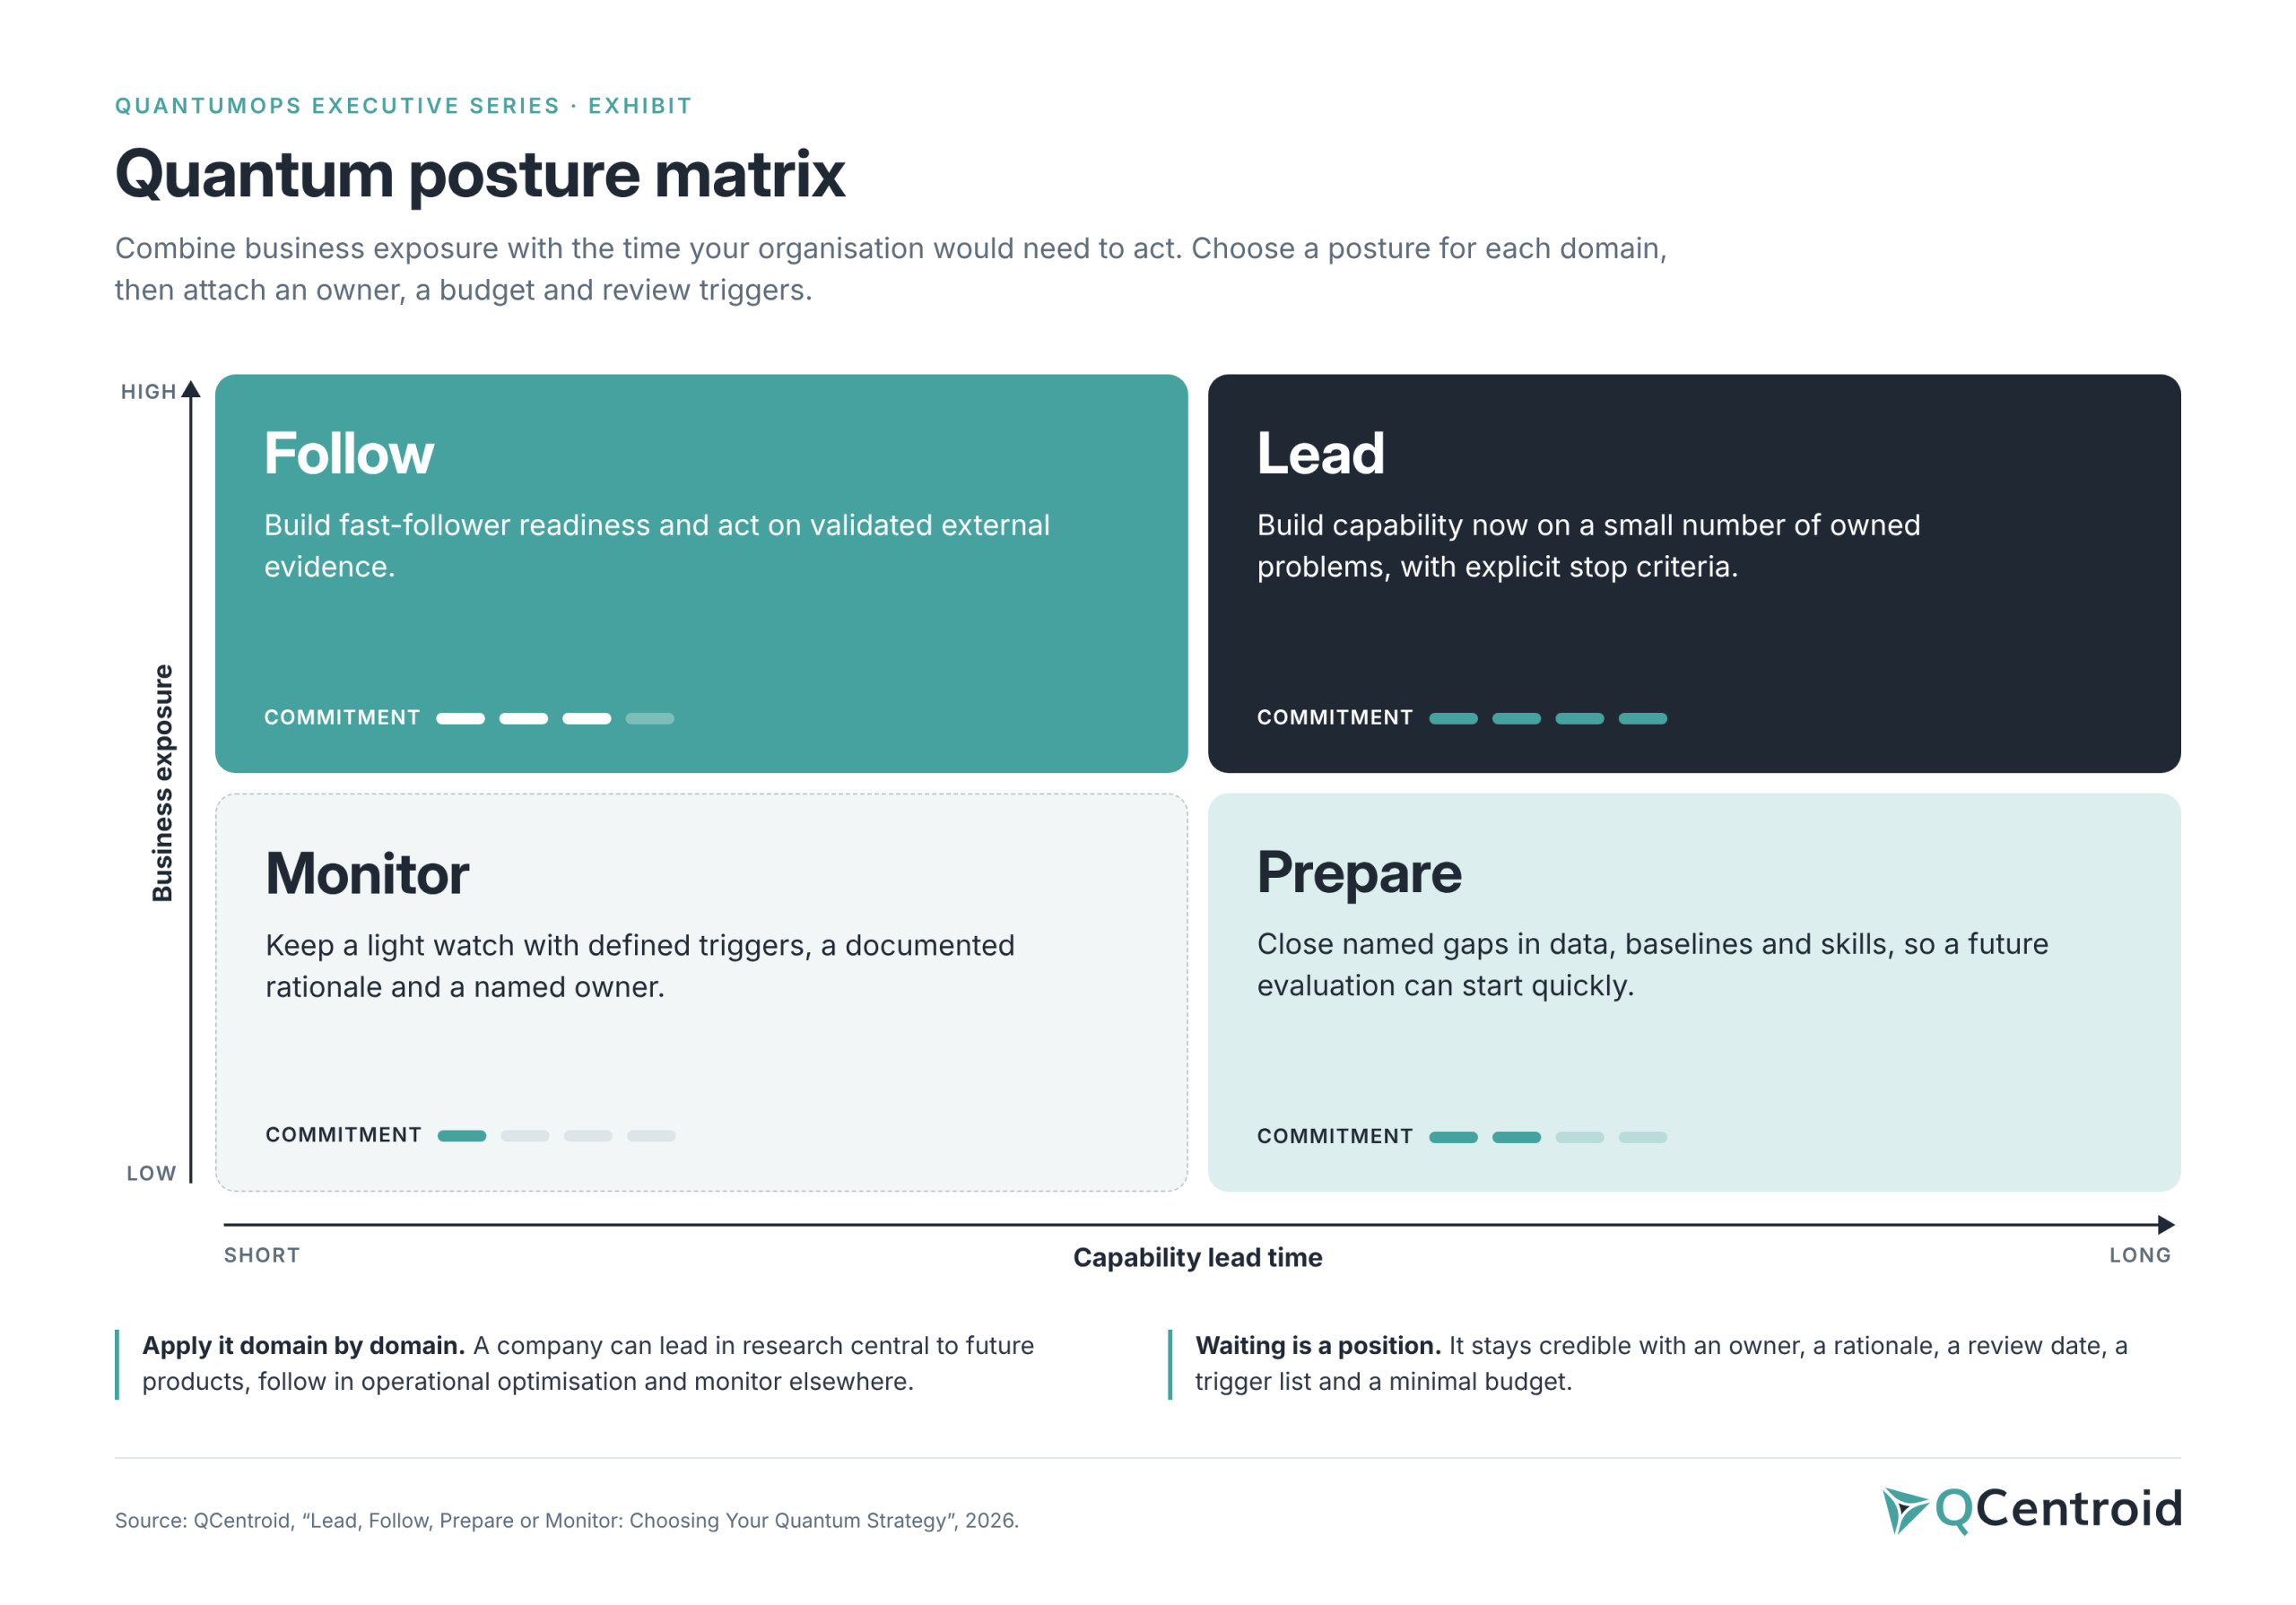
Combining exposure with lead time gives four postures. Each is the correct choice for a particular combination, and none is a measure of ambition. Apply the matrix domain by domain. A single posture for the whole enterprise usually overstates some areas and neglects others.
Exhibit: Quantum posture matrix
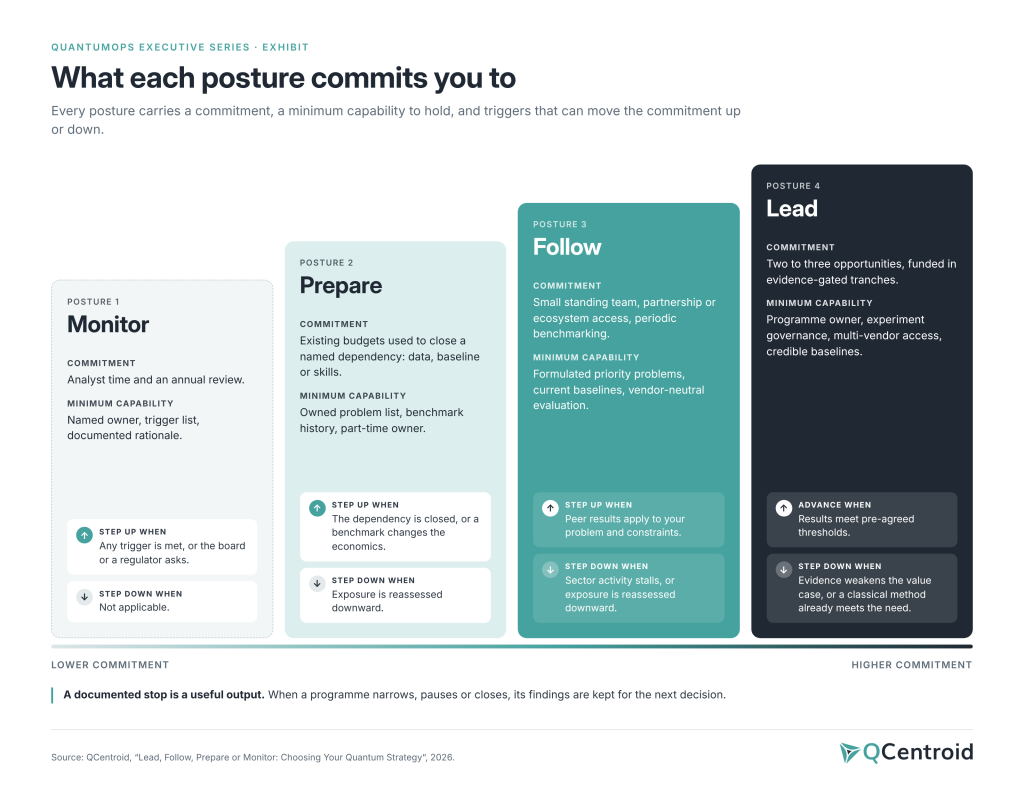
Each posture implies a different commitment. Each also carries triggers that can reduce the commitment as well as increase it.
When a programme narrows, pauses or closes, its findings are kept for the next decision. A documented stop is a useful output.
Three planning horizons for quantum strategy
The chosen posture is easier to govern when commitments follow the organisation’s own planning cycle. Each horizon is a planning scenario with conditions attached. None of them is a prediction.
Current budget cycle. Approve only work whose purpose and cost can be specified now. Typical items are an inventory of computationally constrained decisions, classical and GPU benchmarking of the most important ones, a named owner and governance path, and confirmation that cryptographic migration is tracked. Each item should produce an output that supports a named decision.
Next investment period. List the opportunities that become investable when specific evidence appears. That evidence could be a result against a tuned baseline, a hardware performance or cost threshold, or validated adoption by a peer. State what evidence would release funding and who approves it.
Longer strategic horizon. Record the developments that would change the posture itself, such as fault-tolerant machines at useful scale or a regulatory change affecting the sector. Treat supplier roadmap dates as assumptions to test, and name an owner for each signal.
Scheduled reviews should be combined with these triggers, so that a material development gets attention between meetings.
How to prepare for quantum computing without a dedicated budget
The prepare and monitor postures can be funded almost entirely from existing budgets.
Problem inventory. Enterprise architecture and business owners list the ten most computationally constrained decisions, with current methods, costs and baselines.
Continuous benchmarking. These problems are reassessed periodically against improving classical, GPU and AI methods, using existing cloud and HPC budgets. Efficiency gains are reported as classical improvements. They fund themselves and build the evidence history that a future quantum decision will need.
Governance. Quantum becomes a standing agenda item in an existing forum, such as the architecture board or technology radar.
Each of these assets transfers directly if a domain later moves to follow or lead. A decision to wait stays credible as long as five things are maintained: an owner, a documented rationale, a review date, a short trigger list and a minimal monitoring budget.
Example: a telecoms operator planning network capacity
Consider a telecommunications operator examining network capacity planning. The business owner sees potential value in better capacity allocation. However, the team has no strong baseline on representative network data, and improvements to the existing optimisation process already have an approved business case.
The CIO chooses prepare for this domain. During the next quarter, the planning and data teams build a representative dataset, document the current baseline and identify the interfaces a future evaluation would need. A named technology owner tracks relevant external evidence.
Management agrees a trigger for moving to follow: a credible external result that makes a specific approach worth testing under the operator’s own constraints. At that point, a capped evaluation tests whether the approach adds value after data handling, execution and integration costs.
The operator now has a reasoned position, useful work for the quarter and a defined route to its next decision. The preparation also strengthens its existing optimisation programme.
Quantum strategy actions for the next quarter
Draft a one-page position memo.Owner: CIO/CTO office. For each domain, cover exposure, chosen posture, budget envelope, triggers and review date. State the main alternative considered. Agree it with business owners, finance and architecture before presenting it at the executive committee. If the question was minuted, file the memo with the board secretary.
Build the problem inventory.Owner: enterprise architecture with business owners. List the ten most computationally constrained decisions, with current baselines and owners. This underpins every posture.
Separate the cryptographic track.Owner: CISO. Confirm that post-quantum migration is planned and reported on its own track, and include a status line in the position memo.
Success after one quarter is easy to recognise. When anyone asks “what are we doing about quantum?”, the organisation answers with a documented position, an owner and a date.
Part of the QuantumOps executive series by QCentroid: practical guidance for leaders building a repeatable, governed approach to advanced computing.
The fundamental allure of quantum technology lies in a law of physics: it is impossible to observe a quantum system without changing it. In the context of communication, this means any attempt at interception is immediately detectable. This “observer effect” has turned quantum R&D into a high-stakes race, drawing intense interest not only from military commands but also from industries where data integrity is the lifeblood—most notably global banking and critical infrastructure.
In 2025, quantum technology decisively transitioned from theoretical physics into engineering standards and national security doctrines. For defense and aerospace firms, this marks the end of venture-backed experimentation and the beginning of rigid deadlines for infrastructure migration.
Historically, defense-funded “moonshots” have been the primary engines for civilian technological revolutions (the internet and GPS being the most prominent). We are seeing this pattern repeat today. As governments pour billions into national security agendas, they are effectively subsidizing the “Silicon Valley” of the 2030s, accelerating the development of dual-use technologies that will soon become standard for the general public.
The global quantum defense market has reached $2.9 billion this year, with a projected 14% CAGR, according to BIS Research. The primary driver is the urgent need to address GPS vulnerabilities and the “harvest now, decrypt later” threat to sensitive data with 20+ year secrecy requirements.
Key Areas of Dual-Use Quantum Technology
To cut through the noise, we evaluate quantum readiness using Technology Readiness Levels (TRL). This distinguishes between marketing “moonshots” and operationally deployable systems.
By 2026, the risk of retrospective decryption has become a standard line item in defense risk assessments.
Quantum communication provides what is known as Information-Theoretic Security. Unlike current encryption, which relies on the mathematical difficulty of factoring large numbers, Quantum Key Distribution (QKD) relies on the physical properties of light.
PQC (Post-Quantum Cryptography): NIST standards are now finalized. As of April 2026, deadlines to submit migration plans for US federal agencies are coming into force.
QKD (Quantum Key Distribution): While China nears the 2027 launch of its “Dawn” geostationary satellite, the EU’s EuroQCI has activated its first commercial segments to secure cross-border government data.
Quantum Sensing & Navigation (TRL 6-7: Field Testing)
In modern electronic warfare, GPS signals are easily jammed or spoofed. Quantum sensors (specifically, atom interferometers) enable “Inertial Navigation” with zero drift. SIPRI notes that many of these technologies are reaching operational readiness. The U.S. Defense Intelligence Agency confirms that sensing and communications are approaching battle-ready maturity.
The Solution: Quantum accelerometers and atom interferometers allow for navigation based on Earth’s gravitational and magnetic anomalies.
Business Impact: By eliminating the “drift” inherent in classical Inertial Measurement Units (IMUs), submarines and UAVs can maintain centimeter-level precision for months without an external signal.
The “No-Bullshit” Reality:SWaP (Size, Weight, and Power) constraints remain the bottleneck. These systems are currently viable for large platforms (frigates, strategic bombers) but are not yet miniaturized for tactical loitering munitions.
Quantum Scenario Simulations & Digital Twins (TRL 5–6: Active Piloting)
Classical Monte Carlo simulations are hitting a “complexity wall” in multi-domain operations. Quantum modeling allows mapping massive probabilistic variables directly onto quantum states to simulate outcomes in real time.
The Direction: Defense labs, including AFRL, are piloting quantum-enhanced simulation for materials and chemistry R&D — the aim is to shrink the candidate space that classical methods must screen, and, with it, the multi-year discovery cycle. What’s not yet public is an audited, end-to-end time-saving: results so far are speed-ups on specific sub-problems, not program-level metrics.
Dual-Use Impact:
Defense: Modeling “Fog of War” iterations, accounting for simultaneous kinetic, cyber, and electronic warfare disruptions.
Banking: Utilizing “Black Swan” market simulations to optimize capital reserves and systemic risk far beyond classical Value-at-Risk (VaR) models.
The Status: Moving from lab-bench theory to active field pilots.
Quantum Optimization & Logistics (TRL 4-5: Pilot Stage)
Using hybrid quantum-classical algorithms to manage complex theater logistics.
The Reality: Optimization is where defense interest is highest, and proven advantage is thinnest. Hybrid quantum-classical solvers are being piloted for theatre logistics, but published results remain problem-specific and rarely beat well-tuned classical solvers at scale.
The Benchmark That Matters: This is precisely what DARPA’s Quantum Benchmarking Initiative exists to settle. QBI runs in three stages (A → B → C); as of late 2025 it is in Stage B, where 11 companies are assessed against a 2033 utility-scale target, with independent verification & validation (Stage C) still ahead. Until that verdict lands, headline optimization percentages are vendor claims, not validated benchmarks.
Who’s Leading — Companies & Collaborations
Quantum Computing Firms
There isn’t a single “finalist” list yet, but the industry is focused on DARPA’s Quantum Benchmarking Initiative (QBI). The following teams have advanced to Stage B—the deepest public cut to date—aiming to produce utility-scale systems by 2033:
Nord Quantique – Superconducting with bosonic error correction.
Photonic Inc. – Optically linked silicon spin qubits.
Xanadu – Photonic quantum computing.
Note: Quantinuum also provides “Quantum Origin” for hardened encryption keys, while D-Wave continues to supply quantum annealers for logistics optimization to defense actors like Lockheed Martin.
Quantum Sensing & Navigation
Q-CTRL (Australia) — Ironstone Opal, magnetic-anomaly navigation. Field-validated in air, land and maritime trials, with DARPA and DIU contracts for next-generation sensors; the Royal Australian Navy’s MV Sycamore field-tested the system for shipboard navigation in GPS-jammed and GPS-spoofed conditions. In flight trials it outperformed the best competitive alternative by over 100x. Separately, the Australian Army has used Q-CTRL’s Fire Opal on convoy routing — a problem that can take over a month of classical computation for 120 convoys.
SandboxAQ (US) — AQNav/MagNav. Holds a US Air Force contract for magnetic navigation; flown for 150 hours across the continental US aboard Airbus subsidiary Acubed’s flight-lab aircraft, producing continuous position fixes inside the FAA’s 2-nautical-mile en-route requirement and reaching ~550 m accuracy 64% of the time.
Worth stating plainly: both are magnetic-map matching plus AI, not cold-atom interferometry. The two get conflated in coverage and have completely different SWaP profiles and maturity curves.
Quantum Security & QKD Specialists
ID Quantique (Geneva, Switzerland, acquired by IonQ) provides QKD systems, quantum-safe networking, and hardware-based quantum random number generators—deployments include early QKD for Swiss elections and record-breaking fiber QKD
Quintessence Labs (Australia) develops QKD systems and quantum-secure hardware for generating randomness, backed by Australian Government defense grants.
LuxQuanta (Barcelona, Spain) — continuous-variable QKD (NOVA LQ), designed to coexist with classical optical traffic on existing fiber infrastructure. Coordinator of the EU-funded QUARTER program and, since July 2026, QUARTERNEXT — a four-year effort to mature CV-QKD into certifiable, industrial-grade systems under the EuroQCI mandate. That is a certification project, not a research demo — which is the harder and more consequential step.
Quside (Barcelona, Spain) — high-speed quantum random number generation. Within QUARTERNEXT, it supplies the QRNG entropy for cryptographic key generation across the consortium’s stack. Entropy is the least glamorous layer and the first thing certification bodies audit.
Public & Government-Funded Initiatives
Beyond startups, defense giants and alliances are operationalizing these technologies.
Thales: Adopting a “pragmatic engineering” approach, Thales is deeply integrated into EuroQCI and is a key player in NIST’s PQC standardization (co-authors of the Falcon algorithm). Their focus is strictly on deployable cold-atom sensors for GPS-denied environments.
Indra: leading NATO REPMUS exercises to validate QKD interoperability in the maritime domain, and managing the rollout of secure comms in Spain and Portugal.
NATO: The alliance has formally adopted a “Quantum-ready” strategy. The focus is interoperability—ensuring that a quantum sensor on a British frigate can communicate with a US command center. The DIANA accelerator is now aggressively funding dual-use quantum pilots to bridge the “valley of death” between lab and battlefield.
BAE Systems (UK): partnered with Infleqtion and QinetiQ on the UK MoD’s quantum navigation flight trials at Boscombe Down, testing an optical atomic clock and cold-atom inertial components aboard QinetiQ’s RJ100 demonstrator. In September 2025, BAE’s FAST Labs signed a three-year agreement with the US Air Force Research Laboratory on quantum sensing and networking, focused on combining multiple quantum RF sensors into arrays. Quantum Navigator
Safran (France): the useful counterweight. Safran Electronics & Defense’s head of R&T for inertial navigation puts a possible introduction of quantum technologies more than ten years out, and the company has focused development on hemispherical resonator gyroscope (HRG) technology instead, on the grounds that quantum-based technology is not yet mature enough. When a prime with skin in the game says “not yet,” that is stronger evidence on TRL than any vendor deck. Aerospace Testing International
Leonardo (Italy):active in EU Quantum Flagship sensing consortia and Italy’s national quantum programme, alongside its role in European PNT partnerships.
Global Trajectory & Regulatory Landscape (2026)
Region
Strategic Priority
2026 Regulatory Milestone
United States: From “Benchmarking” to Utility
The U.S. strategy has pivoted from experimental theory to industrial-scale engineering.
DARPA’s QBI: The Quantum Benchmarking Initiative (QBI) is now in a critical phase, aiming for fault-tolerant, utility-scale systems by 2033.National Standards: The NIST Post-Quantum Cryptography (PQC) standards are now the mandatory benchmark for federal agencies, forcing a massive private-sector migration to quantum-resistant encryption.
China: The QKD Superpower
Global QKD Coverage
Record Breakers: In early 2025, Chinese teams achieved a world-record 12,900 km quantum-secured link via satellite.The “Dawn” Satellite: China has announced the 2027 launch of “Dawn,” the first geostationary quantum satellite, which will provide 24/7 uninterrupted quantum coverage, bypassing the 9-minute window of current LEO satellites.
European Union
Strategic AutonomyThe EU is treating quantum as a critical infrastructure project to avoid dependency on U.S. or Chinese tech.
The European Quantum Act: proposal expected in 2026, with the Act itself now targeted for 2027.EuroQCI & Eagle-1: The European Quantum Communication Infrastructure (EuroQCI) is moving from pilot to operational status this year, supported by the launch of the Eagle-1 satellite to secure the bloc’s government communications.
India / Russia
Sovereign Standards
India’s Rapid RiseIn late 2025, India’s DRDO successfully demonstrated long-distance free-space QKD. This highlights a shift where “second-tier” quantum powers are skipping legacy infrastructure and moving straight to quantum-secure satellite communications.Russia: Indigenous Standards & Industrial PilotsRussia’s focus is on technological sovereignty, specifically developing domestic alternatives to Western standards.Indigenous PQC: Russia is developing its own quantum-resistant standards, such as theShipovnik (Rosehip) algorithm. Russia frames this as protection against what it describes as potentially backdoored Western standardsHardware Roadmap: Rosatom has reported the completion of 50-qubit processors based on ions and neutral atoms, focusing on nuclear logistics and supply chain optimization.
Switzerland
Sovereign niche, regulator-led
Switzerland sits outside the EU and EuroQCI, so it is building its own posture. Its first national quantum strategy (Swiss Quantum Initiative, March 2026) flags the absence of a national QKD network and urges one that could later interconnect with EuroQCI. On the regulatory side, FINMA Guidance 05/2026 (July 2026) asks supervised financial institutions to hold a PQC migration roadmap by mid-2027 — aligned with the pan-European “Securing Tomorrow, Today” statement. On the ground, the Geneva Quantum Network (launched November 2025 by IonQ with CERN, Rolex and the Swiss government) is the country’s first dedicated quantum network.
Reality-check corner – 2026
To make informed investment decisions, it is vital to acknowledge what quantum cannot do today:
Breaking RSA-2048: Still impossible. To crack current encryption, we need millions of physical qubits with error correction. We remain in the NISQ (Noisy Intermediate-Scale Quantum) era, with a current ceiling of 1,000+ qubits.
Run outside a hybrid workflow: In 2026 the QPU is one accelerator inside a hybrid quantum–classical pipeline, not a standalone machine. Classical HPC still carries most of the load and orchestrates the quantum step; the near-term production model is hybrid, cloud-delivered Quantum-as-a-Service (QaaS), not on-premise quantum replacing your HPC.
On-Premise Costs: The overhead of cryogenic cooling and specialized maintenance makes on-premise hardware non-viable for most contractors. The immediate future is Quantum-as-a-Service (QaaS) via secured clouds (Azure, IBM, AWS).
Looking Ahead: Predictions for Industry Trajectory
Timeframe
Expected Quantum Impact in Dual-Use
Now (0–2 years)
Quantum utility through hybrid quantum-classical systems: PQC deployment on the finalized NIST standards, QKD pilot links, early field trials of quantum sensors, and benchmarking schemes.
Potential fault-tolerant quantum systems supporting advanced AI, global QKD networks, and material R&D.
Closing Thoughts
Quantum in defense is a cycle of protection and optimization.
The communication layer (PQC now, QKD where it actually earns its place) is the part with hard deadlines; sensing and optimization are still proving, problem by problem, where they beat classical methods. The organizations that come out ahead won’t be the ones with the best slide decks — they’ll be the ones that knew which algorithms to migrate first, which pilots were worth funding, and which vendors would still be standing in five years.
QCentroid was built to help organizations make decisions with evidence rather than hype. Through our QuantumOps platform, defense and dual-use teams can test quantum and hybrid workflows against their real use cases, benchmark hardware across providers, and do it all in an environment that meets their security and sovereignty requirements.1
If any of this is on your desk right now, let’s talk.
Building a quantum strategy has become urgent for organisations that weren’t ready for how fast quantum investment arrived. Many now have a quantum position before they have a quantum programme.
Which leaves a lot of organisations expected to have a quantum position before they have a quantum programme.
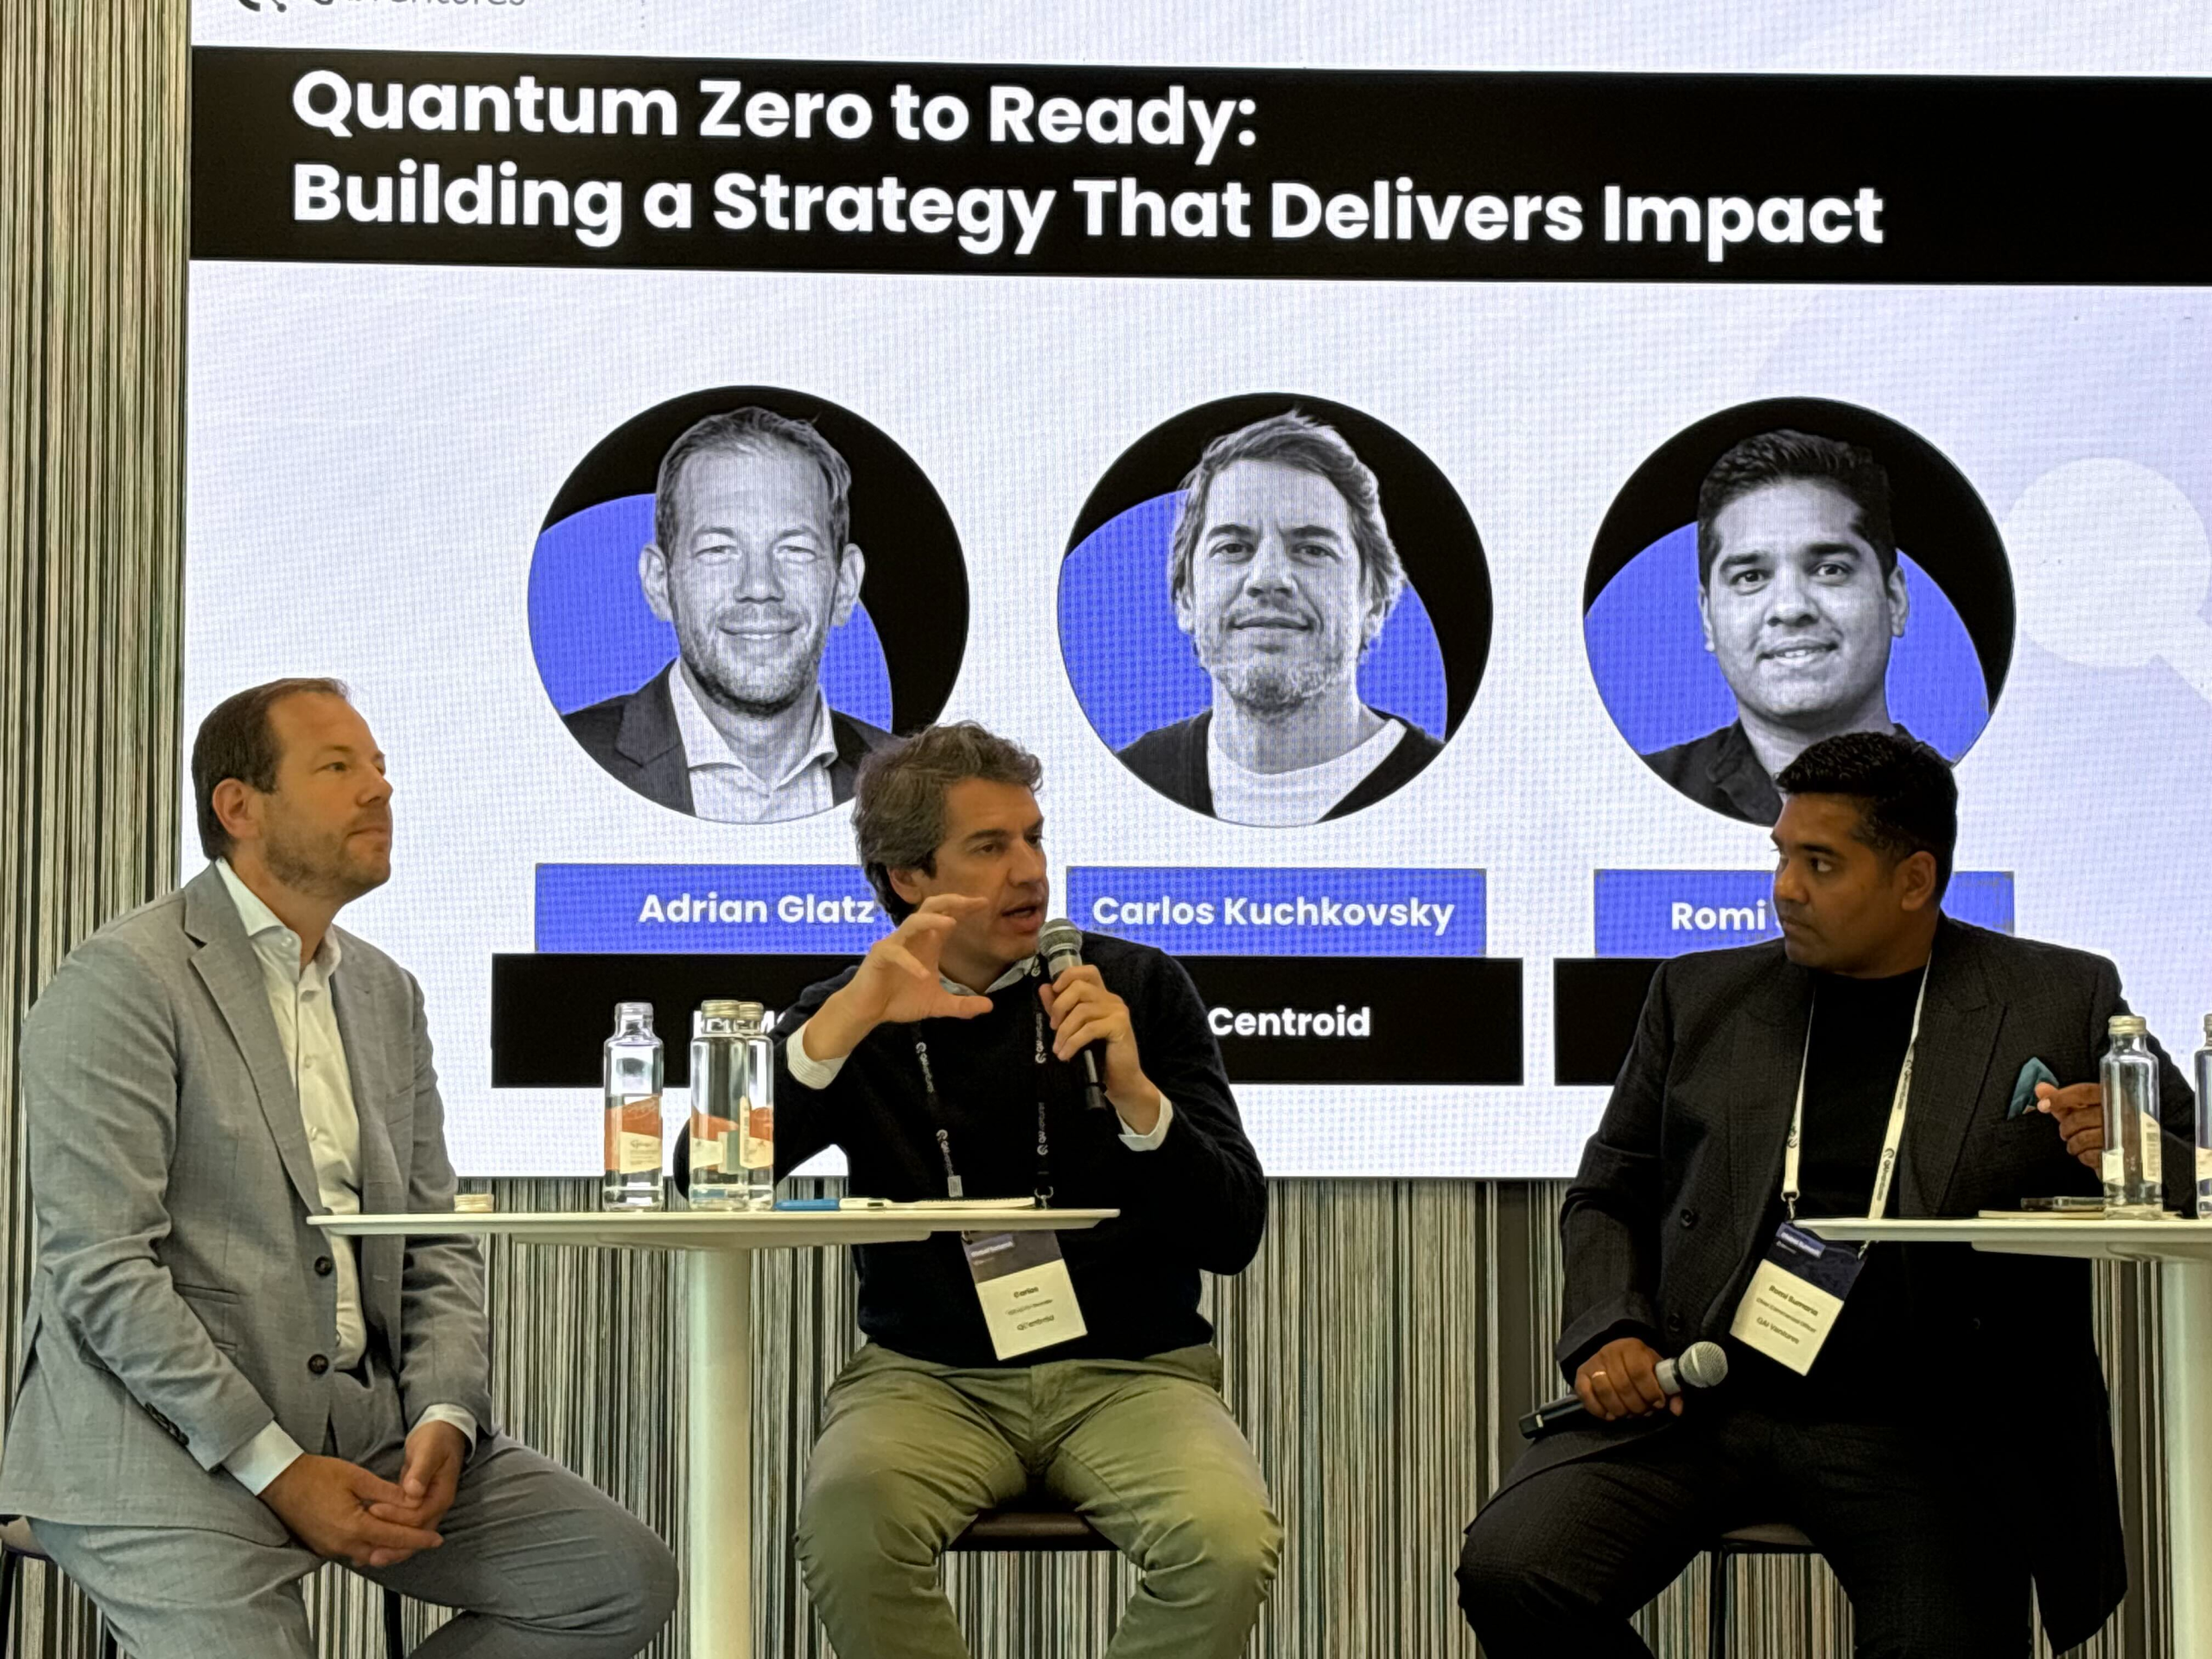
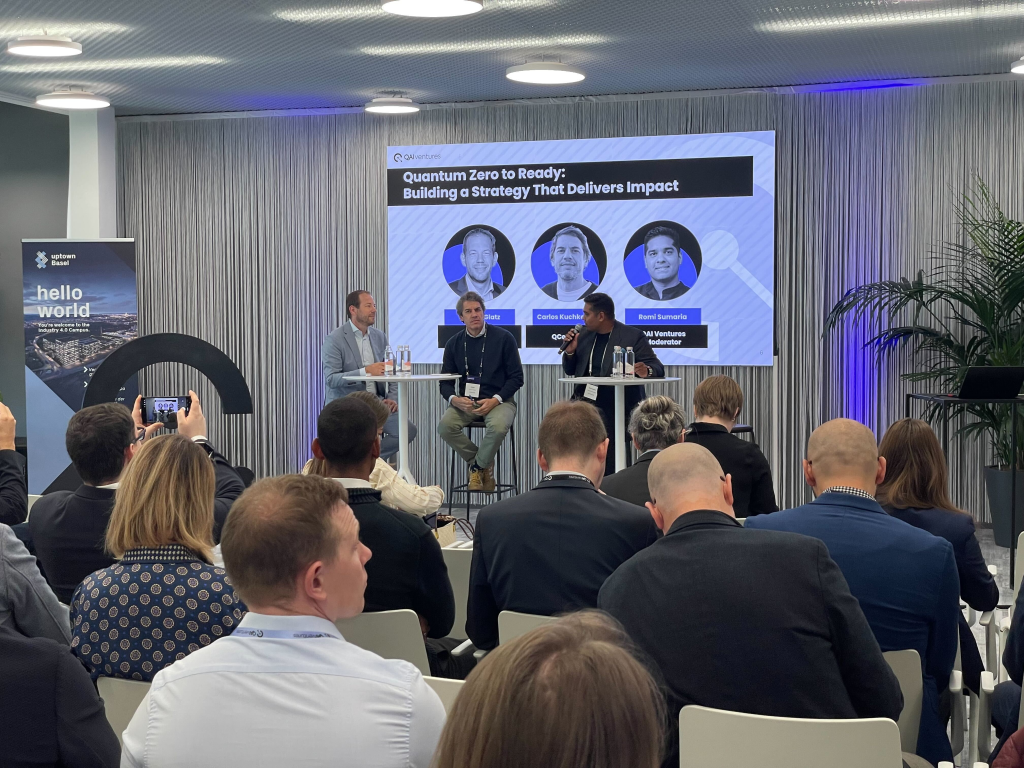
Carlos Kuchkovsky, CEO and Co-Founder of QCentroid, spoke about that gap at the Quantum Global Summit in Basel, in the session From zero to ready: building a strategy that delivers impact, alongside Romi Sumaria, Chief Commercial Officer at QAI Ventures, and Adrian Glatz, Partner at KPMG.
His starting point was the business case. A named problem. A KPI the organisation already reports on. A budget line.
The use cases and technical requirements may look very different across industries. But the path from zero to a quantum programme that can demonstrate business relevance — and survive a budget cycle — is remarkably similar.
That path starts by identifying problems worth solving, understanding how they are solved today, testing different approaches and building evidence around where quantum can add value.
Seven founders from the 2026 accelerator cohort graduated at the summit. Two years ago, QCentroid was in that seat.
Today, QCentroid provides the platform behind the QAI Ventures industry sandboxes, where organisations can explore sector-specific use cases in their own context, test what makes sense for them, and use that evidence to build the roadmap that comes next.
From being part of the accelerator to helping other organisations take their first structured steps into quantum.
A nice reminder that quantum readiness is not about having all the answers. It is about building the capability to find them.
How QCentroid QuantumOps uses expert AI agents and NVIDIA CUDA-Q to start from proven classical baselines, design evidence-driven hybrid experiments, and recommend where —and whether— quantum computing should become part of an enterprise application.
Beyond algorithm selection
For years, much of the conversation around enterprise quantum computing has focused on algorithms: find a relevant business problem, identify a quantum algorithm that could address it, run it on a simulator or quantum processor, and compare the results.
That is an important first step, but it is not how most enterprise applications are actually built. Real applications are heterogeneous systems. They combine data processing, machine learning, optimization, simulation and business logic, already running across CPUs, GPUs and distributed infrastructure. Introducing quantum computing into those systems is therefore rarely a question of replacing an entire classical application with a quantum one.
The more useful question is where, if anywhere, should quantum computing sit inside an application that already works? This shifts the focus from quantum algorithm selection to hybrid application engineering. The objective is no longer simply to demonstrate that a quantum algorithm can solve a problem. It is to determine experimentally whether a quantum component contributes value, where it should be introduced, how much of the application should become quantum, and which computational resource should execute it.
In many cases, particularly in the near term, the resulting architecture will probably be hybrid. In others, continued experimentation may be justified while waiting for more capable quantum hardware. And sometimes the evidence will simply say keep it classical for now. All of these are valid outcomes.
This is the next stage of the QuantumOps approach described in our previous article. Once a classical baseline and a candidate computational problem exist, the challenge becomes engineering the boundary between classical and quantum computing—and accumulating enough evidence to make that boundary defensible.
Figure 1. The Enterprise Hybrid Application Cycle: starting from an existing classical application, alternative hybrid architectures are progressively designed, executed and compared until sufficient evidence exists to support an architectural recommendation.
Start from what already works
Hybrid quantum engineering should begin with a classical baseline, not with a quantum algorithm. The baseline establishes what an alternative architecture must compete with in terms of output quality, computational cost, execution time, scalability and operational requirements. More importantly, it provides a working application that can be progressively modified.
Rather than asking how to build a quantum version of an application, the engineering team can ask which parts of the existing application are actually worth changing. This distinction becomes particularly relevant outside optimization, where there may not be a single obvious solver or computational component to replace.
The QATALIZE project, currently being implemented by QCentroid and Gradiant using CESGA’s HPC and quantum infrastructure, provides a useful example. One of its objectives is to explore a generative AI approach to materials discovery using a conditional Generative Adversarial Network, or cGAN.
Materials discovery involves searching extremely large chemical spaces. In the catalyst use case, candidate materials can ultimately be evaluated using Density Functional Theory (DFT), but those calculations are computationally expensive. The generative model acts as a pre-screening mechanism: it learns from existing data, generates promising new candidates, and reserves expensive downstream evaluation for a much smaller subset. The same architecture can also target materials for CO₂ capture by changing the training data, chemical representation and conditioning targets.
The interesting question for hybrid computing is therefore not simply whether this GAN can be made “quantum”. It is where quantum computation should intervene inside it.
Hybrid engineering creates three levels of decision
What initially looks like a single decision—whether to use quantum computing—quickly separates into several architectural questions. In practice, there are at least three levels that must be navigated systematically.
Level 1 — Which application component?
The first decision is where quantum computing could plausibly contribute to the overall application. An industrial workflow may include data preparation, optimization, simulation, machine learning, inference and post-processing, while only a subset of those components may justify quantum experimentation.
In the QATALIZE materials-discovery example, the candidate component is the generative model used to navigate the chemical search space. Identifying that component, however, does not define the hybrid architecture.
Level 2 — Where inside that component?
Finding a promising component still does not tell us where its classical–quantum boundary should be. A GAN contains a Generator and a Discriminator, each composed of multiple transformations and layers. In the architecture being explored in this project, quantum experimentation is focused on the Generator. The Generator is the initial focus because it directly controls the learned representation used to explore the candidate space, making changes in its latent transformation measurable through downstream candidate-quality metrics.
The engineering question becomes much more granular: at which point inside the Generator should a quantum transformation be introduced? A parametrized quantum circuit (PQC) could operate close to the latent input, after an initial classical transformation, inside a compressed bottleneck, later in the network, or potentially at several points.
The architecture is therefore no longer simply classical versus quantum. It becomes a spectrum of possible hybrid designs.
Level 3 — On which computational resource?
Once a hybrid architecture has been defined, a third decision remains. The quantum component may initially run through GPU-accelerated simulation, then under simulated noise, and eventually—if the evidence justifies it—on a QPU. Different QPUs may themselves become alternative experimental targets.
These three decisions are related, but they are not interchangeable. Together, they define an increasingly large design space:
What to make quantum → where to make it quantum → where to execute it.
Hybrid application engineering therefore quickly stops being a single quantum experiment and becomes an experiment management and decision problem.
Figure 2. Hybrid quantum engineering introduces decisions at different levels of abstraction, from choosing the application component to defining the classical–quantum boundary and finally selecting the execution resource.
Finding the classical–quantum boundary inside a GAN
The QGAN experiment makes this design problem particularly visible. The classical baseline can be represented as a conventional Generator that transforms noise and conditioning information into a candidate material, while a classical Discriminator evaluates generated samples during training.
The conditioning signals describe what the researcher is looking for—for example, a target adsorbate and an adsorption-energy range—while the Generator learns to propose candidates consistent with those conditions.
Starting from that baseline, several alternative Generator architectures can be explored. A quantum transformation close to the latent space introduces a PQC early in the Generator, allowing the quantum component to operate on an initial representation of the latent variables. A quantum bottleneck first uses classical layers to transform or compress that representation, passes the resulting compact state through a PQC, and then expands it again through classical layers. A later quantum transformation allows classical computation to build a richer intermediate representation before applying the quantum transformation. More complex designs can introduce several quantum layers at different positions.
The architecture has deliberately been designed to support this flexibility: classical and quantum layers can be interleaved, while the number, depth and position of quantum components remain configurable.
Each architectural alternative then introduces further experimental parameters, including the number of qubits, circuit depth, encoding strategy, parametrized ansatz, training configuration and execution backend. The search space cannot be expanded arbitrarily: increasing qubit count or circuit depth may introduce trainability, gradient-estimation and sampling costs that must themselves become part of the experimental evidence. Hybrid application engineering becomes a search problem of its own. The question is no longer simply which quantum algorithm to use, but where quantum computation belongs within the application architecture.
To make these comparisons meaningful, the experimental design must also control for factors that could otherwise confound the results. Classical and hybrid architectures should be evaluated using consistent datasets, conditioning targets, training budgets and evaluation procedures, with repeated runs across controlled random seeds to account for training variability. Where architectures differ in model capacity, factors such as trainable parameter count, circuit evaluations and computational resources should also be tracked. The objective is not simply to find the best-performing configuration, but to determine whether an observed improvement can reasonably be attributed to the architectural change being tested.
Figure 3. Examples of candidate Generator architectures. The surrounding application remains unchanged while the position of the quantum component becomes a controlled experimental variable.
Why systematic experimentation matters
Even a deliberately simplified experiment already creates multiple evaluation paths:
Generator architecture
Classical/GPU training
GPU quantum simulation
Noise-aware simulation
QPU experiment
Classical baseline
✓
—
—
—
Early quantum layer
✓
✓
✓
Selected
Quantum bottleneck
✓
✓
✓
Selected
Late quantum layer
✓
✓
✓
Selected
Multiple PQCs
✓
✓
✓
Selected
Legend: ✓ indicates a normal evaluation stage for that architecture; — means that the stage does not apply to the classical baseline; “Selected” means that QPU execution is not performed automatically for every configuration. Only architectures that produce sufficient evidence in earlier simulation and benchmarking stages are shortlisted for hardware validation.
And this matrix is still highly simplified. A single row may contain multiple circuit configurations, training parameters, random seeds, problem sizes and dataset variants. Experiments may need to be repeated to measure training variability, while each execution target introduces additional constraints and measurements.
The challenge is therefore not merely running a quantum circuit. It is maintaining enough structure across all those experiments to determine whether moving the PQC improved the generated candidates, whether that improvement remains under more realistic execution conditions, what additional computational cost it introduces, whether the result is reproducible and whether the architecture remains technically feasible as the problem scales.
Without systematic experimentation, it is relatively easy to produce an interesting quantum result while still lacking enough evidence to support an application decision.
Figure 4. QuantumOps turns alternative hybrid architectures and their execution configurations into structured experiments rather than independent, manually coordinated runs.
CUDA-Q makes the execution target an experimental variable
This is where NVIDIA CUDA-Q becomes an important enabling technology. CUDA-Q provides a unified programming model for hybrid applications in which CPUs, GPUs and QPUs work together, and its backend model includes CPU and GPU simulators as well as supported quantum hardware targets.
For hybrid neural-network workloads, CUDA-Q also provides an integration pattern with PyTorch, allowing classical neural processing and quantum components to coexist inside the same workflow. The architectural consequence is more important than any individual API: changing the computational target does not necessarily require redesigning the overall application architecture.
Without a common execution layer, moving an experiment from one target to another can easily become an integration exercise involving different SDKs, interfaces and infrastructure. That friction makes systematic comparison harder because part of the engineering effort is spent changing technology rather than testing the hypothesis.
With CUDA-Q, a promising hybrid Generator can instead be evaluated progressively across GPU-accelerated quantum simulation, noise-aware experimentation and selected QPU execution, with evidence from each stage feeding back into architecture and circuit design, while preserving the same underlying application hypothesis. CUDA-Q provides GPU-based noisy simulation capabilities as well as multiple simulation strategies designed for different circuit characteristics and scales.
Different backends do not become equivalent. Hardware constraints, topology, noise, circuit characteristics and execution behavior still matter and need to be measured. The important difference is that these characteristics can become experimental variables rather than architectural barriers.
The less engineering effort a team spends switching execution technologies, the more effort it can spend determining whether the alternative architecture is actually better.
Figure 5. CUDA-Q decouples the hybrid application hypothesis from the execution target, allowing the same quantum component to be evaluated across accelerated simulation, noise-aware simulation and quantum hardware. Results from each execution environment can feed back into architecture and circuit design, making the process iterative rather than strictly sequential.
A real heterogeneous environment: HPC and QPU
The QATALIZE infrastructure provides a natural environment in which to apply this methodology. CESGA operates conventional HPC capabilities alongside Qmio, a quantum-computing research environment that includes a 32-qubit superconducting QPU and HPC resources connected to the quantum infrastructure.
This matters because hybrid applications are inherently heterogeneous. Dataset preparation, classical neural-network training and large experimental campaigns remain natural HPC/GPU workloads. Quantum components can be simulated on accelerated classical infrastructure and, where the evidence justifies doing so, selected configurations can advance to quantum hardware.
The objective is not to migrate the workload from HPC to quantum computing. It is to determine how classical, accelerated and quantum resources should cooperate within the same application. That is a fundamentally different adoption model.
From execution to evidence: the role of QuantumOps
CUDA-Q reduces the friction involved in constructing and executing heterogeneous experiments, but easier execution creates another challenge: more architectures and configurations are now feasible to explore.
As circuit parameters, datasets, Generator designs and execution targets multiply, the engineering team needs to preserve the relationship between the hypothesis being tested, the configuration executed and the evidence produced. This is the role of QCentroid QuantumOps.
QuantumOps structures the experimentation cycle around the computational infrastructure, managing alternative configurations, executions, results and benchmarking information so that experiments become comparable rather than isolated runs. Expert AI agents operate over this experimental context to assist particularly across execution, benchmarking and recommendation. Their role is not to make the architectural decision autonomously, but to help teams navigate the design space, identify meaningful comparisons, detect weak experimental branches, interpret accumulated evidence and suggest which configurations deserve further investigation. The final decision remains with the user.
In this sense, CUDA-Q and QuantumOps address different but complementary layers of the problem: NVIDIA CUDA-Q makes heterogeneous computing programmable, QCentroid QuantumOps makes heterogeneous architectures experimentally comparable and evidence-driven.
Figure 6. QuantumOps preserves the evidence behind each architectural alternative, allowing expert agents and users to compare experiments and determine which branches deserve further investigation.
From experimental evidence to architectural recommendation
For the QGAN experiment, infrastructure metrics such as runtime and resource consumption are necessary but not sufficient. The central question is whether modifying the Generator improves its ability to propose useful material candidates.
Because the exact project evaluation framework will evolve with the implementation, a practical starting point is to focus on three complementary metric families that are widely aligned with evaluation practices in generative chemistry and materials discovery.
The first is candidate validity rate: the percentage of generated outputs that satisfy the chemical and structural constraints required by the representation. Validity is a standard dimension in generative molecular benchmarks, where the objective is to distinguish models that generate syntactically or chemically meaningful candidates from those producing unusable outputs. For QATALIZE, the exact validity rules can be adapted to the catalyst or MOF representation being generated.
The second is novelty and diversity. A generative model that repeatedly reproduces known candidates may achieve high validity while contributing little to materials discovery. Novelty measures whether generated candidates differ from the training set, while diversity or uniqueness captures whether the model is exploring different regions of the design space rather than repeatedly generating near-identical candidates. These dimensions are also commonly included in molecular generation benchmarks.
The third—and ultimately the most application-oriented—is a DFT-validated target hit rate: among the candidates selected for downstream validation, what proportion actually satisfies the target physical criteria, such as falling within the desired adsorption-energy window? Materials-generation research increasingly evaluates generated structures against target properties and validates promising candidates using first-principles calculations or experimental measurements rather than relying exclusively on ML-level metrics. For this use case, improving that hit rate would directly support the original objective: reducing the number of expensive evaluations required to find promising materials.
These three measures should be interpreted together with engineering evidence such as training stability, execution time, computational cost, required qubits, circuit depth and sensitivity to noise. A hybrid Generator that produces a marginal improvement in candidate quality at dramatically higher computational cost may not justify its complexity, while a configuration that is promising under ideal simulation but highly noise-sensitive may be better classified as a future candidate than as an architecture ready for QPU execution today. For an enterprise architecture, experimental performance must ultimately be evaluated alongside operational criteria such as integration complexity, reproducibility, reliability, security, deployment constraints and total computational cost.
At the end of the cycle, QuantumOps and its expert agents can help consolidate the experimental evidence into an architectural recommendation. The evidence may show that the classical Generator remains the best option; identify a particular quantum bottleneck as promising enough for continued simulation; show that an architecture has potential but should wait for more capable or lower-noise hardware; or justify advancing a specific configuration to QPU validation.
The important point is that none of these outcomes is predetermined. The purpose of the process is not to find quantum advantage. It is to find the right computational architecture. In that context, keep it classical for now is not a failed quantum experiment but an evidence-based engineering decision.
When quantum does become part of the recommended architecture, the team should be able to explain not merely that a quantum experiment worked, but why that component was selected, why the classical–quantum boundary was placed there, what alternatives were evaluated, what evidence supports the decision and which computational resources are appropriate for executing it.
Engineering the boundary
Enterprise quantum adoption is unlikely to happen through a sudden transition from classical applications to quantum applications. It is more likely to emerge progressively inside heterogeneous systems, with CPUs, GPUs and QPUs performing the parts of a workload for which they are best suited.
The real engineering challenge is therefore not choosing between classical and quantum computing. It is finding the right computational boundary between them.
The QGAN materials-discovery project illustrates that challenge particularly well. Even after identifying the Generator as the candidate for quantum experimentation, multiple architectural questions remain: where to introduce the PQC, how much of the network to make quantum, how to configure it, how to execute it and how to determine whether the change produced meaningful value.
NVIDIA CUDA-Q provides the heterogeneous programming and execution foundation that makes this type of exploration practical. QCentroid QuantumOps provides the experimental framework around it: structured execution, benchmarking, evidence accumulation and AI-assisted recommendations.
Together, these capabilities shift the conversation beyond the quantum algorithm: from asking “Can we run this problem on a quantum computer?” to asking “Where should quantum computing participate in this application—and what evidence supports putting it there?”
An operational pattern for enterprise hybrid quantum-classical workflows — from a business problem to a reproducible, comparable benchmark.
Enterprise quantum computing is moving past the isolated demo. For a growing number of teams the question is no longer “can we run a quantum algorithm?” It is a harder, more operational one: how does a team get from a business problem to a reproducible hybrid quantum-classical workflow, compare approaches fairly across classical, GPU-accelerated and quantum backends, and keep improving the experiment as hardware, solvers and understanding of the problem evolve?
That is an operations problem, not only an algorithms problem. It is the problem QCentroid’s QuantumOps practice is built around, and this article is about the operating model. The implementation details come from running QuantumOps at QCentroid with NVIDIA CUDA-Q as the execution substrate, but the pattern is meant to generalize.
The enterprise bottleneck: from idea to executable, comparable workflow
Most enterprise quantum initiatives begin with a promising use case: portfolio or risk analysis, routing, scheduling, energy-system optimization, materials or molecular simulation, or fraud detection. Between that first business question and the first trustworthy benchmark sit a series of unglamorous steps: the problem has to be translated into a technical formulation; a data schema defined; a classical baseline chosen; quantum or hybrid approaches mapped to executable models; backends configured; experiments tracked; and results compared in a way business, technical and research stakeholders can all read.
Without an operating framework, that work scatters across notebooks, scripts, SDKs, spreadsheets and ad-hoc reports. The scatter produces some recurring failures:
Reproducibility. Seeds, shot noise and optimizer initialization move results run-to-run; without recorded controls, a number is an anecdote, not a measurement.
Comparability. Results are hard to line up across solvers, backends and time when each run is configured by hand.
Legibility. Decision-makers cannot tell whether progress is real, measured and worth the next round of scarce, costly hardware time.
A QuantumOps approach treats quantum experimentation as a managed lifecycle that also governs how agents and people collaborate — who proposed a step, who approved it, and what actually ran — so these failures are designed out rather than fought repeatedly.
Figure 1. Benchmarking jobs: reproducibility and comparability across solvers, datasets and backends.
The QuantumOps cycle
QCentroid structures enterprise adoption as a continuous experiment cycle — Define → Model → Execute → Benchmark → Learn → Iterate — where each step produces artifacts that can be versioned, reused and compared. (The cycle itself is the subject of the first article in this series; here it is the spine the agents and the substrate hang on.)
Figure 2. The QuantumOps cycle: Define → Model → Execute → Benchmark → Learn → Iterate.
A team starts by defining the use case: objective, constraints, datasets, expected outputs, the relevant KPIs and the business metric that will decide success. The problem is then modeled into a formal specification (an optimization model, a QUBO, a Hamiltonian, or a variational/hybrid routine) with an explicit input/output schema so that what is being solved is unambiguous and portable across teams. Candidate solver paths are selected (classical baseline, quantum-inspired, GPU-accelerated simulation, QPU validation), executed as tracked jobs, and benchmarked against a stated baseline. The team then learns from a comparable record and iterates. The value compounds: each experiment joins a growing evidence base that says what changed, why a result moved, and which configuration is worth testing next.
Figure 3. The QuantumOps journey and its per-stage tools across the platform.
QuantumOps: the harness for expert quantum agents
QuantumOps is the harness. It is the operating environment the expert quantum agents run in, it gives them the lifecycle to move through, the registry and traceability to record what they do, governed access to compute and data, and the guardrails that keep an accountable human in control.
QCentroid has developed and integrated a set of expert quantum agents into the platform, one for each step of the cycle, so a team can go from a business problem to a benchmarked result without re-inventing the workflow. Because the harness is what provides the lifecycle, governance and execution, it is not tied to those agents alone: the same cycle can drive expert agents created externally, by a customer’s own team, a partner, or the wider ecosystem, under the same controls. The harness is agent-agnostic by design; QCentroid’s agents are the ready-made default, not a lock-in. QCentroid’s broader multi-agent approach to quantum use cases is described here.
The agents do not replace quantum experts and they do not “do” the quantum computing; they remove the toil between a business intent and an executable, well-formed experiment, and keep a human at every decision that costs money or feeds a conclusion. A useful way to read the cycle is one expert agent per stage:
Use-case builder agents. Turn a problem described in natural language into a structured use-case pack: business objective, technical objective, constraints, data schemas, candidate data, expected output, baseline methods, candidate quantum/hybrid approaches, benchmark criteria and success criteria.
Modeling agent. Proposes initial formulations -decision variables, constraints, objective functions and candidate QUBO mappings for optimization; Hamiltonian construction and ansatz families for simulation- for an expert to review and own.
Solver-path & development agent. Recommends candidate execution strategies -classical baseline, quantum-inspired method, GPU-accelerated simulation, a CUDA-Q hybrid workflow, or a QPU-validation step- and when each is worth its cost and generates executable code.
Experiment-design agent. Fixes the benchmark before it runs: which solver versions to compare, which datasets and instances, which backend configurations, which metrics, dependent and independent variables, and which reproducibility controls.
Benchmark-interpretation agent. Summarizes results, technical and business oriented, against the KPIs, baseline and proposes the next iteration: refine the model, change the optimizer/solvers, grow the instance, or compare against a stronger baseline.
The agents scaffold; people decide. That division -automate toil, not judgment- is what makes the loop fast without making it reckless, and it is the governance posture enterprises in finance, energy, healthcare and the public sector actually require.
Figure 4. The agents scaffold; people decide
Figure 5. The use-case / feasibility agent turns a problem statement into a structured, feasibility-checked use-case pack for a human to approve.
Figure 6. The modeling agent’s mathematical definition — objective function, constraints and QUBO formulation rendered from LaTeX, for an expert to review.
NVIDIA CUDA-Q as the execution and resource-access substrate
The agents and the cycle need somewhere to run, and this is where NVIDIA CUDA-Q is load-bearing. CUDA-Q is NVIDIA’s open-source platform and programming model for hybrid quantum-classical computing (it is software, not hardware). That abstraction is precisely what lets QuantumOps keep the science separate from the execution target and the solver portable: the backend becomes a parameter, not a rewrite.
For simulation, CUDA-Q draws on cuQuantum -cuStateVec for dense circuits and cuTensorNet for larger structured ones- so the experimentation engine scales on GPUs before any scarce hardware time is spent. In practice a solver keeps one entry point and selects its backend as a parameter, so the same code path runs in GPU-accelerated simulation during iteration and against a QPU for validation:
import cudaq

@cudaq.kernel
def ansatz(thetas: list[float]):
    q = cudaq.qvector(4)
    h(q)
    # ... problem-specific cost and mixer / variational layers ...

def run(use_case, solver_params):
    #
    # backend is a parameter, not a fork:
    #
    cudaq.set_target(solver_params.get("backend", "nvidia"))
    #   "nvidia" / "tensornet"  -> GPU-accelerated simulation (iterate)
    #   a QPU target            -> hardware validation (promote)
    # build the model, optimize parameters, sample the result
    return result
The point is not the code; it is the property the code has — one solver definition, many targets.
Within QuantumOps, CUDA-Q becomes the managed execution path: a team defines a hybrid workflow, runs it through CUDA-Q on a GPU-accelerated simulator (in QCentroid via the Launchpad, with no local driver or environment setup), captures the experiment’s metadata, compares it with other solver paths, and later validates the same workflow on an available QPU when it is justified. CUDA-Q accelerates and standardizes execution; QuantumOps operates the lifecycle around it. See the companion how-to on accelerating enterprise adoption with NVIDIA CUDA-Q via the Launchpad
Figure 8. Run experiments on multiple devices and accelerated hardware.
How it fits together: from use case to benchmark
Take a domain-neutral example: a combinatorial allocation problem -assign limited resources under business constraints. The work is carried by the set of expert agents acting together across the cycle, not a single one. The builder and modeling agents turn the business description into a use-case pack (objective, technical objective, input/output schema, constraints, baseline methods, candidate approaches, metrics, success criteria) and a candidate formulation (here, a QUBO) for an engineer to review. The experiment-design agent then fixes the benchmark before anything runs:
A fixed objective and a stated classical baseline (for example, a MILP or heuristic) on the same instances.
A fixed instance set and dataset version.
Agreed metrics, typically solution quality against the baseline and time-to-solution.
Reproducibility controls: seeds, restarts the named simulator (state-vector vs tensor-network) and the GPU.
The solver paths to compare: classical baseline, a CUDA-Q GPU-accelerated simulation path, and a candidate QPU-validation path.
Iteration happens in GPU-accelerated simulation; promotion to scarce QPU time is a deliberate, approved step, not a default. Every execution records its inputs, model and solver versions, backend, seeds, code version, logs, cost estimation and results, so a run is a versioned artifact rather than a transient notebook state. Because runs are declarative artifacts, the same experiment can be re-dispatched across backends for an apples-to-apples comparison, and a result from one quarter can be set beside the next without manual reconciliation.
A hybrid, heterogeneous problem
The next phase of quantum adoption is hybrid by design. Enterprises will not use QPUs in isolation; they will combine CPUs, GPUs, GPU-accelerated simulators, quantum backends, classical optimization, AI-assisted development and domain expertise. That makes orchestration, benchmarking and lifecycle management central rather than peripheral -the same concerns that already apply to any serious computational practice:
Heterogeneous resource orchestration. The same experiment may run on a GPU state-vector simulator, a tensor-network simulator, or a QPU — each with different interfaces, capacities and failure modes — scheduled and tracked through one workflow.
GPU-accelerated simulation as the engine. Most iteration happens in simulation, so simulation must scale and the simulation-to-hardware transition must be seamless.
Reproducibility and provenance. Versioned, declarative runs with full provenance, so any result can be re-created.
Cost estimation and energy-aware allocation. Scarce, costly compute means the cost and energy of each path should be estimated and visible before it is spent.
As GPU and quantum hardware move onto shared, low-latency fabric, the boundary between “simulate” and “run on hardware” becomes a configuration choice inside one hybrid program rather than a hand-off between systems. The operating principles above do not weaken in that world; they matter more, because faster and more heterogeneous execution raises the bar for reproducibility and disciplined benchmarking. That is the practical reason to build the practice on a portable and fundamentally hybrid substrate — NVIDIA CUDA-Q — today.
Figure 9. Solver development and deployment cycle
From isolated demos to institutional memory
Enterprise adoption is a disciplined iteration, not a single proof of concept. Teams need to test formulations, baselines, optimizers, ansätze, backends, data versions and problem sizes — and to understand not just which result is best but why, under which assumptions, and whether it reproduces. When a new backend appears, relevant experiments can be re-run; when a better solver is added, it can be compared against historical baselines; when the business problem changes, the use-case pack and schema evolve without losing the prior history. The output of the method is evidence, not anecdote: a versioned record of what was run, against which baseline, on which resource, at what cost, with what result — an institutional memory that informs which problem is worth the next experiment.
The shift is concrete: from “we ran a quantum proof of concept” to “we operate a structured, governed program of hybrid quantum-classical experimentation.” Expert quantum agents lower the cost of entering and moving through the cycle; NVIDIA CUDA-Q provides the hybrid execution and GPU-accelerated simulation that make the cycle fast and portable; QuantumOps is the operating layer — lifecycle, registry, traceability, benchmarking and governance — that turns the two into a repeatable enterprise capability.
Today, expert quantum agents help organizations move faster through the experimentation lifecycle while maintaining governance, reproducibility and comparability. Looking ahead, increasingly coordinated agent systems may automate experiment generation, benchmark execution, model refinement and solver selection, creating the foundations for autonomous quantum laboratories operating at enterprise scale.